

We asked nine AI models an easy-sounding question: what's the median time to resolve a support ticket? Each got three tries, and none got it right.
Now say you're building an AI agent that answers questions like that across a company's CRM, help desk, and call recordings. Before it ships, you'd want to know it gets most of them right.
To check, you need an actual company's data and the right answer to every question you plan to ask.
Real customer data is off limits, for good reason. And the test data you can get your hands on doesn't come with answers.
So we built a company from scratch, down to its CRM, help desk, and call recordings. We generated every record, so we could compute the right answer to every question. Then we pointed nine AI models at it.
The best model got 76.8% of its answers right. The worst got 42.4%. Most of the gaps in between were too small to call.
The bigger jump came in a follow-up, on a separate set of 27 questions. When two of the models got to write and run Python, one went from 8 correct answers to 24. The other went from 1 to 22.
The fake company came out of Era, a generator we built at Eon for exactly this kind of testing. We posted the method and full results in a research paper on arXiv. Here's the short version.
How Era builds a fake company
Era by Eon generates a fictional company from four settings and a seed: industry, size, business model, and the applications the company runs.
Same seed, same company, on any machine. Every evaluation is exactly repeatable.
It starts by building one entity graph:
- Employees, with managers, hire dates, and working hours in their own time zones
- Customers, split into sales territories
- Deals, with their full stage history
- Support tickets, recorded calls, chat messages, and documents
Later records point to earlier ones. A ticket's requester is a contact at a real account. A deal's owner is on the sales team.
The graph also carries the mess of a real company, on purpose. People who left still own records. Some customers appear twice in the CRM, courtesy of the usual typos. There's a large pile of inactive prospects, and a few service accounts that aren't people at all. The paper calls this the texture that separates an operating company from a demo dataset. Anyone who has run an access review will recognize it.
Each application is a simulator that implements the real product's REST API and MCP server. There are 66 of them, including Salesforce, HubSpot, Zendesk, Jira, Gong, Slack, Stripe, S3, and Google Drive. Together they form a digital twin of the company.
A simulator doesn't make up data of its own. It serves its slice of the same graph, in its own product's format. The account on a Salesforce deal is the same account on a Zendesk ticket and a Gong call, so a question that spans systems has one answer. Record IDs follow each vendor's real format, so vendor client libraries accept them.
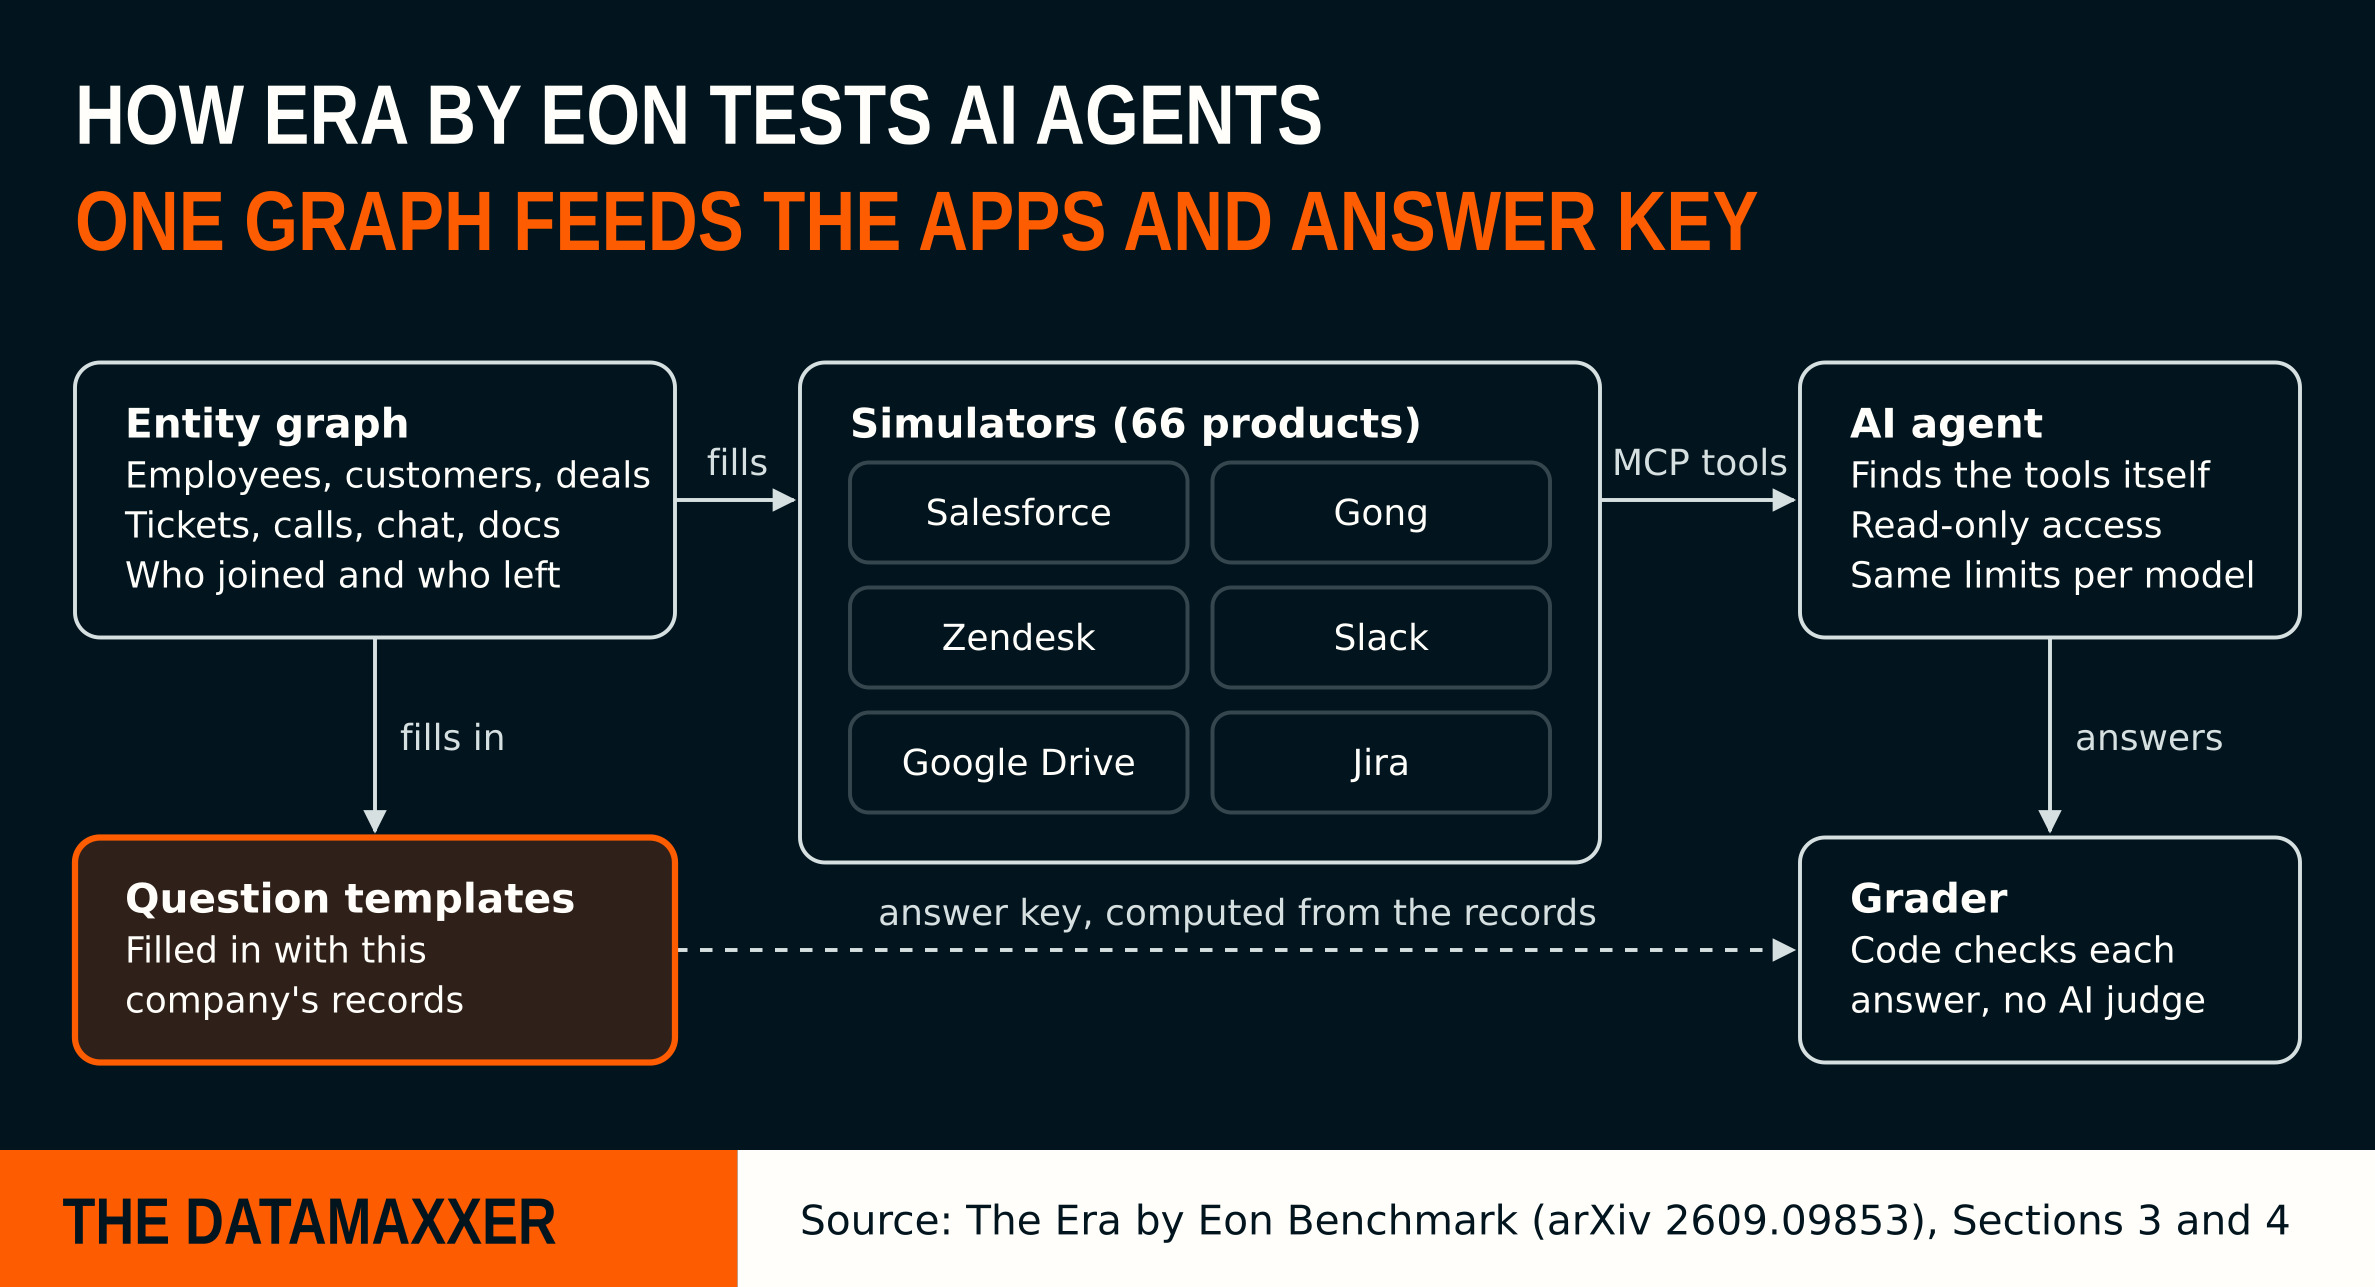
The systems and the answer key come from the same graph, so the answers can't disagree with the data the agent reads.
What's already out there
The usual stand-ins don't get you there. Vendor sandboxes have little data and no history. Hand-built test setups cover one or two systems and are costly to extend.
Research benchmarks get closer. τ-bench, CRMArena, TheAgentCompany, and WorkArena are carefully engineered, and Era builds on several of their design decisions. But each covers a few systems at most. Its tasks are written or curated by hand. Extending it takes real engineering. And the realism of its data is assumed rather than measured.
How every question gets an exact answer
Questions come from templates written in code. Each template pairs a question with the computation that answers it: the total value of the open pipeline, the salesperson with the highest won revenue, the median resolution time of a support ticket.
For each generated company, every template is filled in with that company's accounts and people. Nobody writes an answer by hand.
That also makes the benchmark cheap to extend. A new company needs an industry, a size, and a seed. A new question needs one template, and it applies to every company.
The corpus holds 83 generated companies. A CI test regenerates them from their seeds and checks the output is byte-identical, so the benchmark can't quietly drift as the generator changes.
Twelve composed questions span systems and steps, like the recorded call minutes of the account with the largest open pipeline. Two of the twelve ask for something no system stores, such as a Net Promoter Score. The right answer is to say so. Making one up gets marked wrong.
Three rules keep the questions fair:
- Joins use only keys an agent can see in the products. Gong doesn't expose Salesforce IDs, so calls are matched to accounts by participant email.
- Each question states its own definitions and tie-breaking rule. No model is graded against a convention it was never told.
- If the data doesn't settle a question, say two accounts tie for the largest pipeline, the question is dropped for that company instead of graded against an arbitrary pick.
An answer computed from the graph is correct by construction. It also has to be reachable through the interfaces an agent actually uses.
So an audit reads every answer back through each simulator's API and MCP tools and checks that the values match. It has caught real defects.
One early question joined calls to contacts through an internal record ID. The join worked in the stored data. Through the product it was impossible, because the call system issues its own participant IDs and only the email address shows on both sides. Left in, that question would have penalized every agent that did the right thing.
Generating everything creates an obligation a hand-built benchmark doesn't have: the data has to be shown to look real. So a realism scorecard grades each company on five axes (distributions, correlations, timing, structure, and text) against statistics from Eon's operational data and published sources. An adversarial detector hunts for the tells of generated data, like a customer list that reads Dunn, Dunn2, Dunn3, or the same filler sentence on hundreds of records.
Both were built before the generator was tuned against them. Across 23 companies, five rounds of fixes took the mean realism score from 61.8 to 97.0, and the detector went from flagging 55.2% of records to none. Some checks turned out to be unfair to small companies, so they were fixed and the 61.8 baseline was recomputed under the same scorecard.
The test: 9 models, 33 questions, 3 runs each
We ran nine models on one generated fintech company: 40 accounts, 240 support tickets, and questions over its Salesforce, Zendesk, and Gong data.
There were 33 questions, 21 that need one system and 12 composed. Each model answered each question three times. That's 891 runs.
Each model started with three tools: list the systems, describe a system's tools, and call one. No schemas, no description of the data, and no tool list in the prompt. It had to find the right tool among about 290 on its own, through MCP, the way a deployed agent would.
Every run got its own isolated, read-only copy of the company and the same limits: 25 turns, 40 tool calls, and 8,000 characters per tool response. Any request that would change data is refused, so an agent that tries a prohibited write fails the test, which beats failing the deployment.
Before any question was asked, the harness checked that each simulator served exactly the company's records. A serving bug gets reported as a question not asked, never as a model failure.
Code grades every answer against the key. No AI judge, no partial credit. Each answer declares how it's compared: an exact value, a set, an ordered list, a mapping, or a correct "can't answer."
The full run cost $343.27 at list price.
Most gaps between models didn't hold up
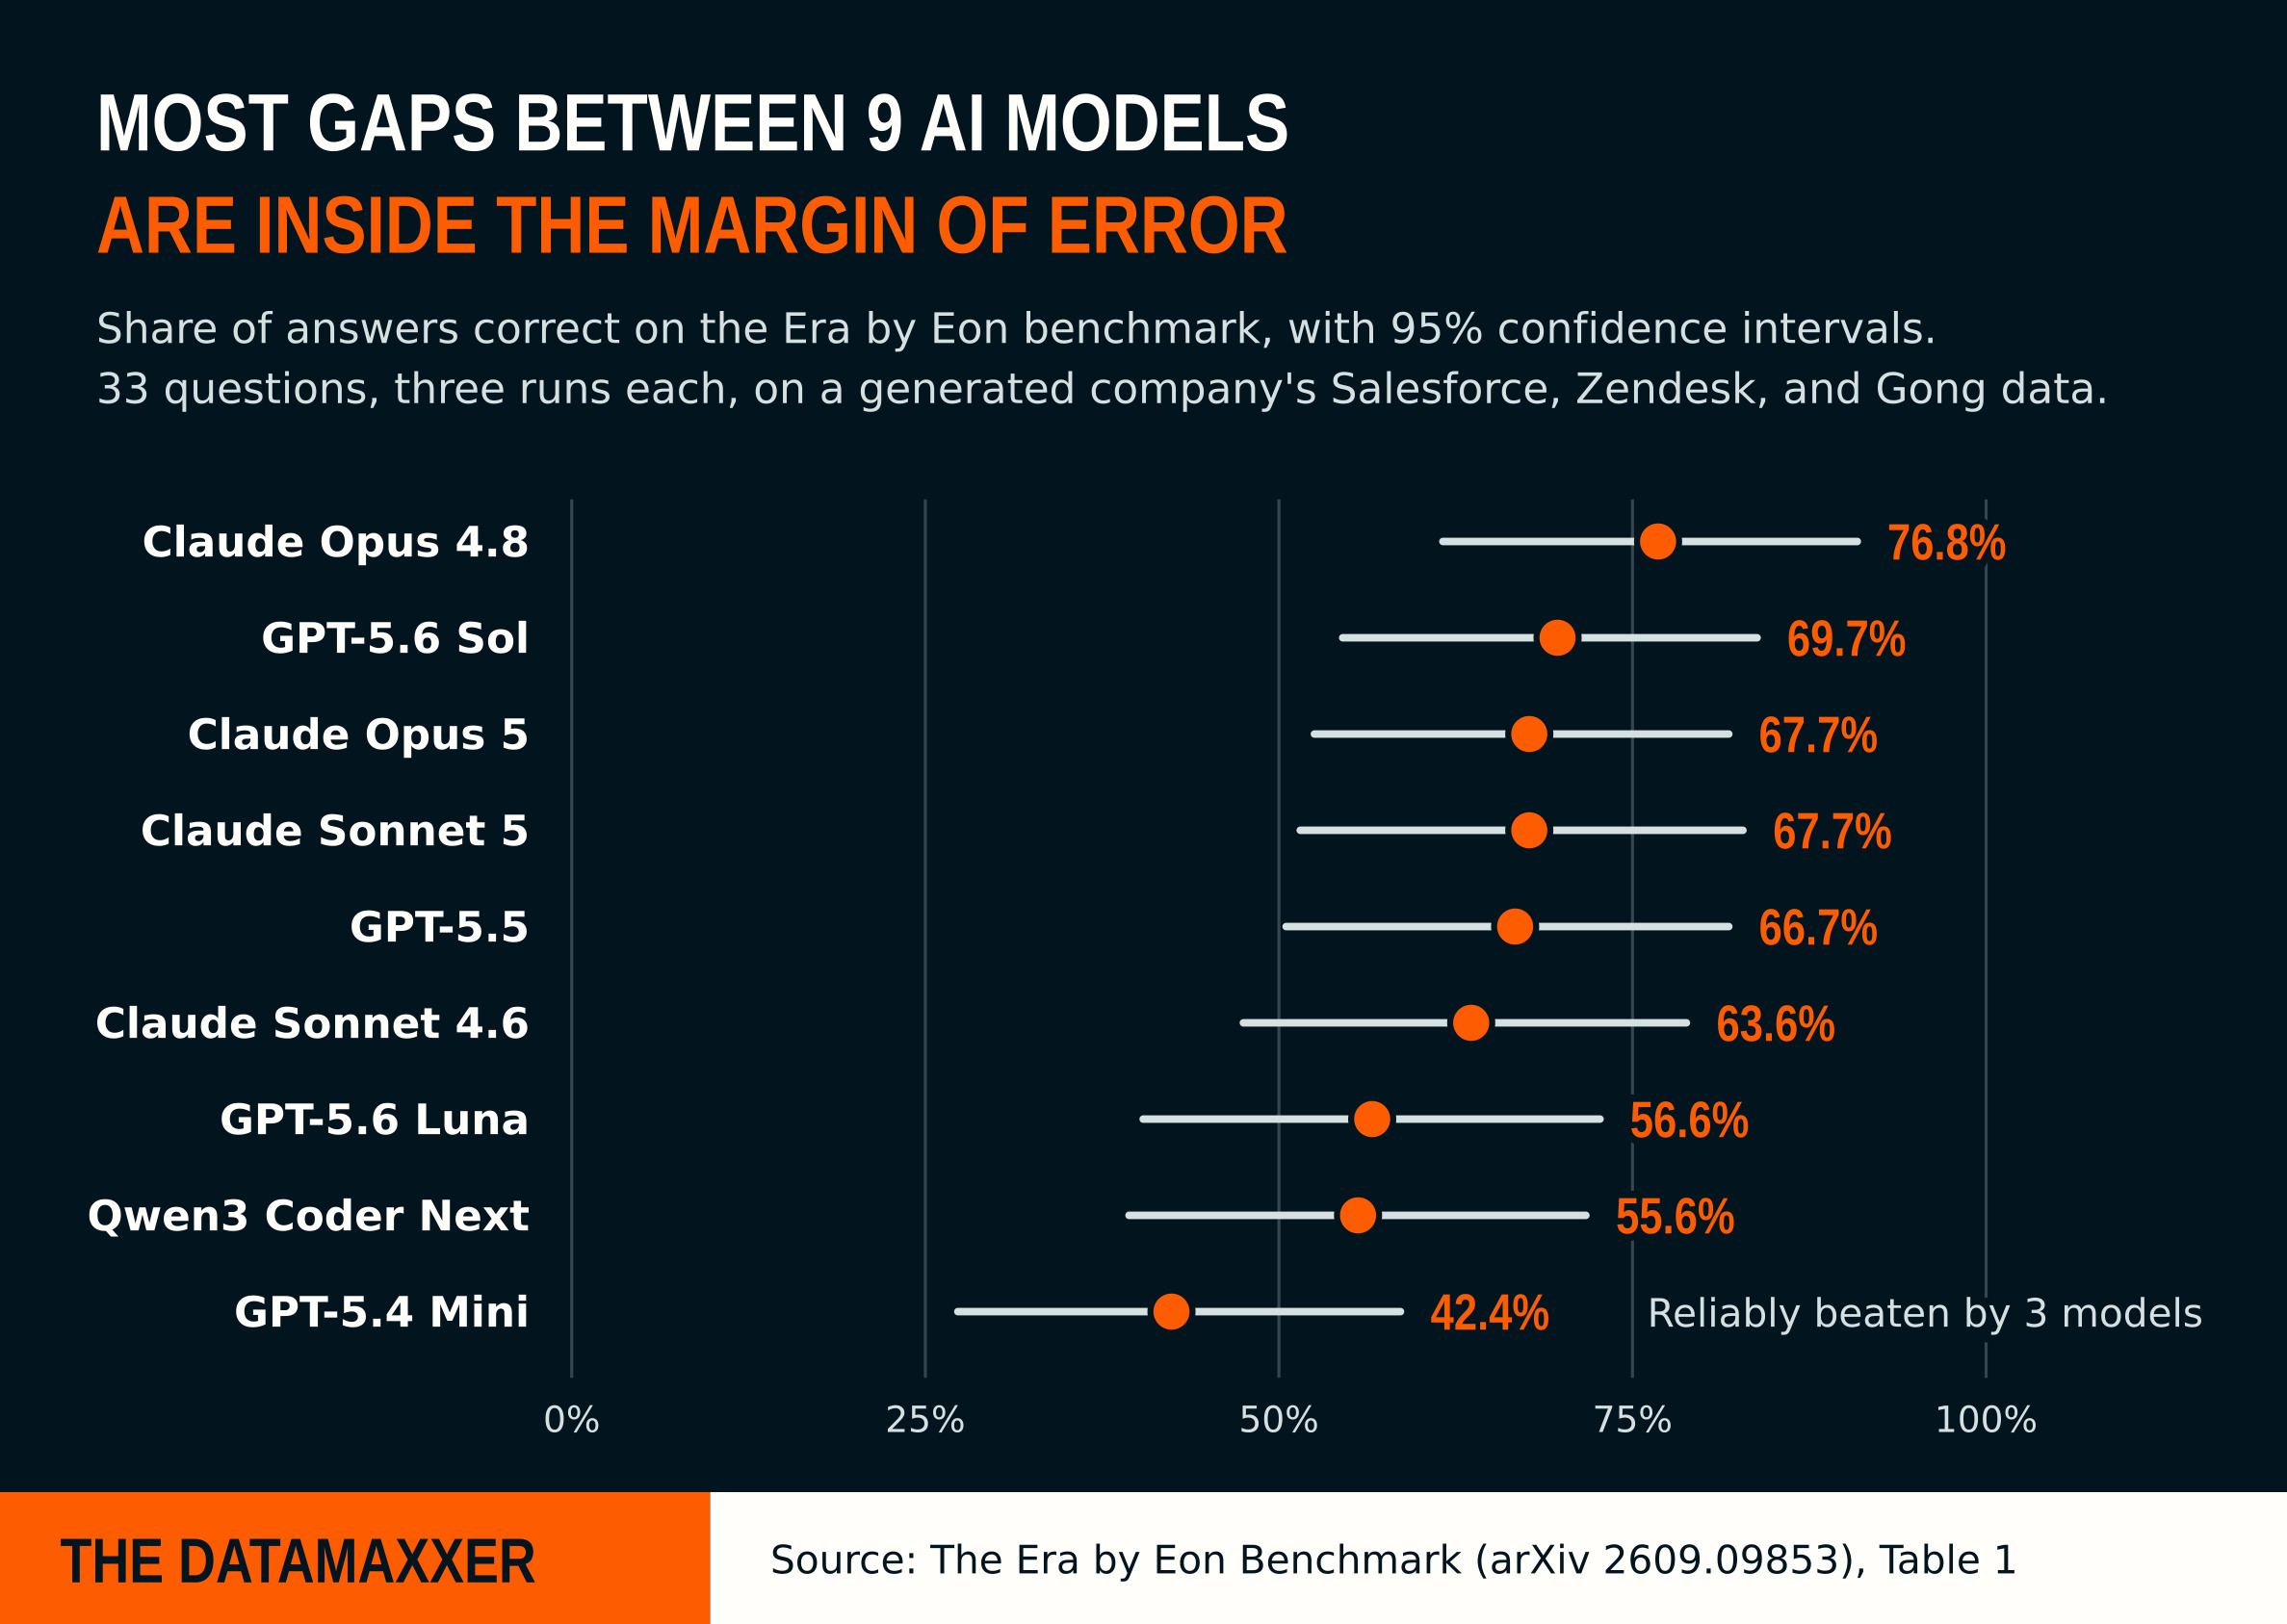
The chart looks like a leaderboard, with Claude Opus 4.8 on top and GPT-5.4 Mini at the bottom.
With only 33 questions, each score's 95% interval is about 30 points wide. We tested all 36 pairs of models, correcting for multiple comparisons. Three pairs differed reliably: Claude Opus 4.8, GPT-5.6 Sol, and Claude Sonnet 4.6 each beat GPT-5.4 Mini.
Every other ordering in that chart could come down to which 33 questions were asked. That's worth remembering the next time a model tops a leaderboard by a few points.
Simple filtering was the easy part. Averaged across the nine models, it was right 92.6% of the time. The difficulty sat in exhaustive aggregation, multi-hop joins, summaries over time, and ordered rankings.
Three questions were among the five hardest for every model: the longest Gong call, total Gong call time, and the ticket priorities for the account with the most tickets. The median ticket question from the top stumped all nine models in every run.
Of the 891 runs, 561 were right, 119 were wrong, 99 declined a question the data could answer, and 112 ended without a usable answer. The totals hide that the models failed in different ways.
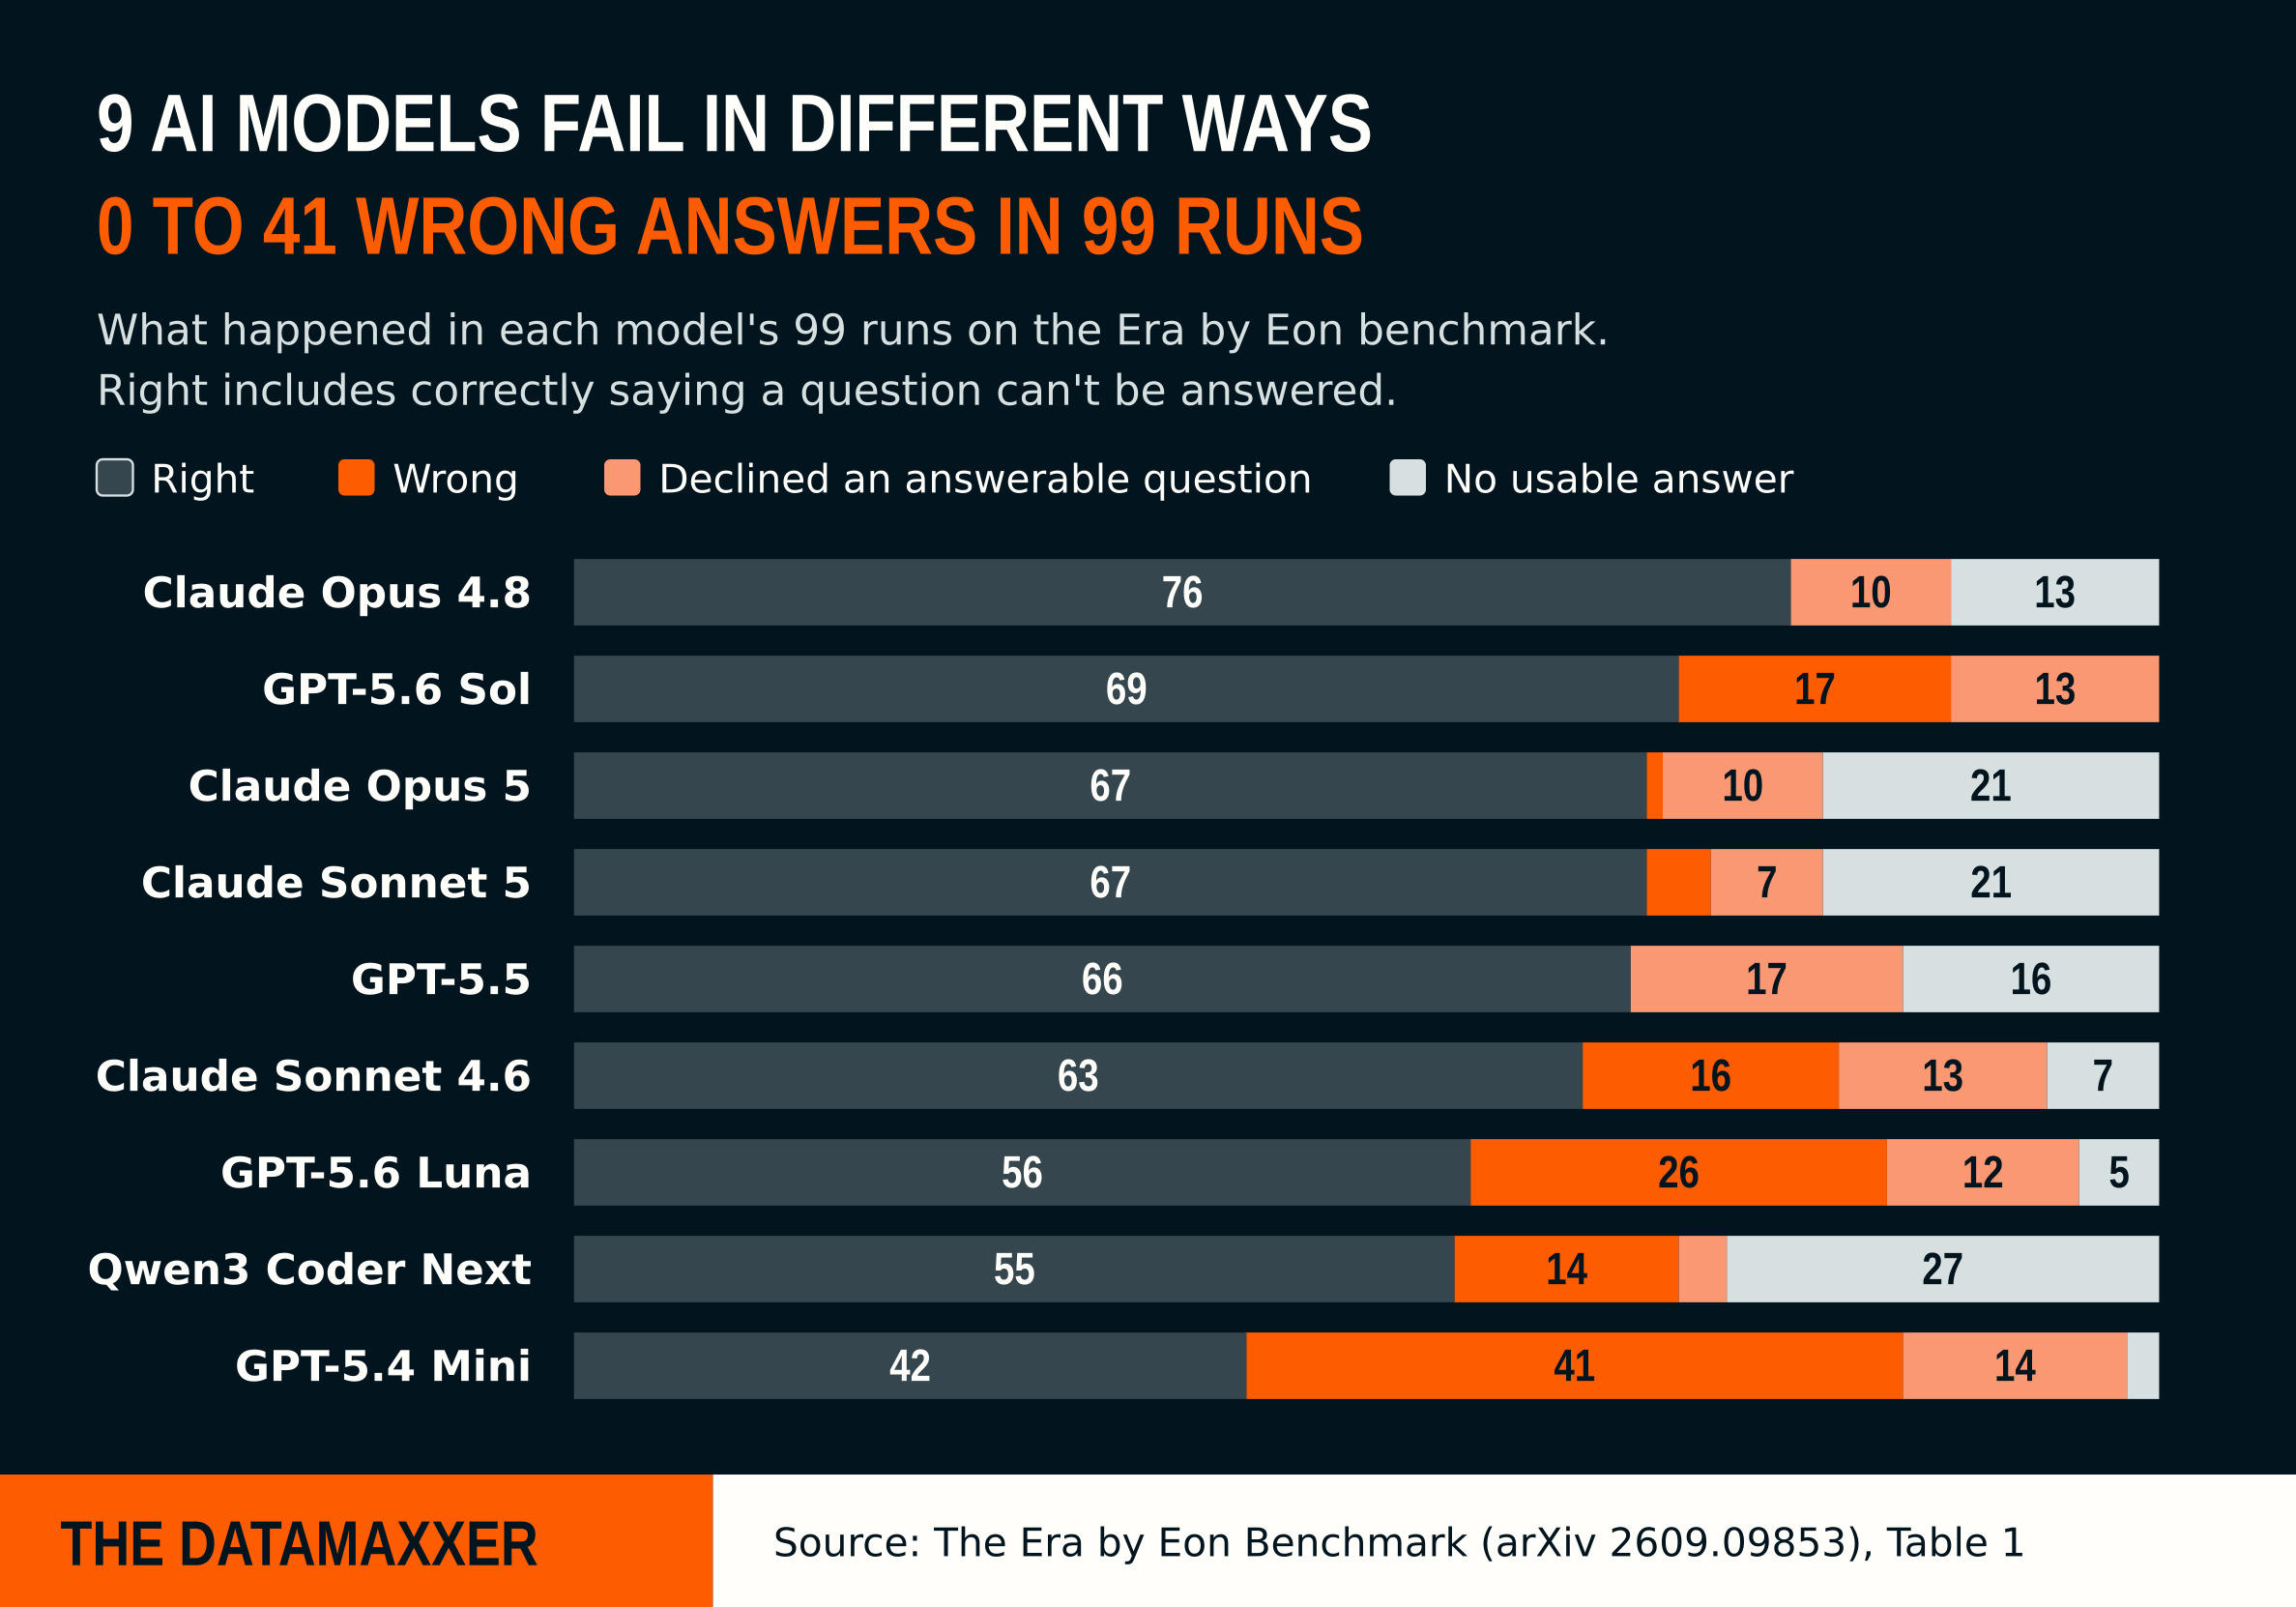
Claude Opus 4.8 gave no wrong answers at all. It also declined or ended without a usable answer in 23 of its 99 runs. GPT-5.4 Mini ended without a usable answer only twice, and was wrong in 41.
Which of those you'd rather have depends on what a wrong answer costs you.
What changed when agents could run code
The benchmark also has a ceiling. In our follow-up paper, we used a larger generated company and an agent program that can run Python. The four strongest of six models answered 22 to 25 of 27 computable questions, one run per question.
Code made most of that difference. The two jumps in the intro were GPT-6 Astra and GPT-5.6 Sol, and their no-code runs already had a much looser budget than ours: 165 turns, 165 tool calls, and up to 32,000 characters per tool result. A script can read every record and hand the model only the result, which the paper says likely explains the jump.
Those scores can't be compared with the ones above, since the company, the questions, and the limits all differ. But on that set, the benchmark barely separated the strongest models.
So the follow-up adds questions built on hidden knowledge: facts that no question or document states. That's a separate story.
Five checks for testing your own agent
Each one comes straight from how the benchmark was built:
- Compute the answer key from the data itself. Not by hand, and not with a model as the grader.
- Include questions the data can't answer, and count a correct "can't answer" as right.
- Join only through keys your agent can actually see in the product, then check that each answer is reachable through the interface the agent uses. Stored data can support a join the product doesn't.
- Run each question several times and report an interval. With a few dozen questions, check whether the gap between two models is bigger than the noise before you switch.
- Count wrong answers, refusals, and runs that hit a limit separately. One accuracy score hides which of them you're getting.
You don't need a copy of production data to start. That's what Era is for. Generate a company to your spec, with your industry, size, and systems, then point your agent at it over MCP or the vendor-compatible APIs. Era is free for builders, and the link is at the end.
Ran it on your own agent? Tell us what broke. We'll publish the best results, with credit.
Limits
- One generated company and 33 question shapes. Three runs per question reduce noise but don't add questions.
- Only the Salesforce, Zendesk, and Gong questions were run. Era can also generate a company's own databases and documents. Those, and the other 82 generated companies, weren't part of this comparison.
- Realism targets come from Eon's operational data and published statistics, and some are estimates. The scorecard measures agreement with the targets. It can't tell whether a target itself is wrong.
- Generated text comes from templates. It can't match the variety of human writing, and a stronger detector than ours might spot it.
- The paper is a preprint under review.
Sources: The Era by Eon Benchmark: A Generated Enterprise Estate with Exact Ground Truth for Benchmarking LLM Agents, arXiv:2609.09853. Era by Eon: Benchmarking Enterprise Agents on Hidden Knowledge, arXiv:2609.30055. Both by Benjamin Gruenbaum, Doron Porat, Assaf Natanzon, Roy Zavida, Chen Dinachi, and Or Itzahary.
Generate a company and connect your own agent: console.era.eon.io
How to cite: In the Era by Eon Benchmark (arXiv:2609.09853), nine LLMs answered 33 questions over a generated company's Salesforce, Zendesk, and Gong data, three runs each. Accuracy ranged from 42.4% to 76.8%, and 3 of 36 pairwise differences held up after correction.
AN
Assaf Natanzon
VP Chief Architect
Co-author of The Era by Eon Benchmark and the hidden-knowledge follow-up.