

We have restored hundreds of terabytes from EBS and RDS snapshots, and the gap between what exists and what can actually be recovered is where teams get burned. AWS snapshot backup is cheap and durable, but its design leaves gaps a schedule alone cannot close.
What is AWS snapshot backup?
AWS snapshot backup is the native point-in-time copy of a storage resource that AWS creates and stores on your behalf. Every snapshot is block-level and incremental, and it lives in the same AWS account and region as the source it was taken from.
Because AWS owns the storage, a snapshot is not a file you can hand to another tool. It is only accessible through the EBS or RDS APIs, and only usable by restoring it back into an AWS resource in the same account.
How AWS snapshot backup works
AWS snapshot backup covers three artifacts (EBS snapshots, AMIs, and RDS/Aurora snapshots), all stored by AWS in S3 and reachable only through the EBS or RDS APIs. The same block-level design sits under all three, and its details decide whether any snapshot restores to something usable.
Consistency: Crash-consistent by default
An EBS snapshot records whatever is on disk when the API accepts the request. Anything still in memory is left behind. AWS Backup freezes all attached volumes at one moment, which matches the volumes but still skips the application.
Application consistency needs a hook before and after the snapshot. On Windows, VSS handles it. On Linux, Data Lifecycle Manager can call a Systems Manager document around each snapshot to run freeze and thaw commands.
Skip that step on a busy PostgreSQL or SQL Server volume and the restored database may replay cleanly or may refuse to start. The engine-by-engine detail is in our guide to backing up databases on EC2.
Restore paths: EBS, AMI, RDS
Every snapshot is block-level at its source, but the restore procedure changes with what AWS bundles around the blocks. Which artifact you took decides the steps you run to bring the data back and where the restore stalls.
Account and region scoping
A snapshot is created in the same account and region as its source, under the same IAM boundary. Cross-region and cross-account copies are separate jobs with their own transfer fees and their own encryption setup.
What AWS snapshot backup costs in 2026
Snapshot pricing sounds simple: pay per GB-month for what you keep. In practice, the bill grows through paths that are not visible on the storage line, and it rarely shrinks in step with the retention policy that's meant to control it.
What you pay for: Changed blocks
The first snapshot stores every written block. Each later one stores only the blocks that changed since the previous snapshot. On a 1 TB volume with 300 GB written, the first snapshot bills for about 300 GB.
The unit of change is a 512 KiB block. One modified byte sends the whole block into the next incremental. On a database volume with scattered writes, that decides whether an incremental is 2% of the volume or 20%.
Later snapshots reference earlier blocks, so a deletion frees only the blocks that belong to that one snapshot. Clearing half the snapshots in an account often moves the bill by a few percent.
Standard and Archive tiers
Standard-tier snapshots cost $0.05 per GB-month in us-east-1, billed on changed blocks stored. Restores from the standard tier are free.
The Archive tier drops storage to $0.0125 per GB-month with three conditions. An archived snapshot is a full copy, a 90-day minimum applies, and retrieval costs $0.03 per GB plus standard storage while restored.
Archive pays off for compliance copies you rarely touch. The deciding factor is snapshot size. Because archive converts an incremental into a full copy, a 20 GB daily incremental becomes a 300 GB full copy and costs roughly 4x more per month ($3.75 vs $1.00).
Archive only saves money on snapshots already close to a full copy: a standalone monthly, quarterly, or end-of-project retention snapshot.
Post-snapshot charges: FSR, Provisioned Rate, RDS
Fast Snapshot Restore is enabled per snapshot, per Availability Zone, and bills hourly for as long as it stays on. A single golden image with FSR enabled across three zones bills every hour of the year.
Provisioned Rate for Volume Initialization, launched in May 2025, is charged per GiB of snapshot data, so a 10 TB restore carries a visible line item. Cross-region copies add transfer charges.
RDS backup storage is free up to 100% of provisioned database storage per region, then bills per GiB-month. Long retention on a high-change database crosses that line fast.
Manual RDS snapshots taken before migrations sit outside any retention window. They stay on the bill until someone deletes them, and in our experience nobody does until the quarterly cost review.
Why storage costs persist after retention cuts
Cutting retention from 30 days to 14 halves the snapshot count, but the storage line drops by a fraction of that. The surviving snapshots still reference most of the blocks.
Encryption adds a second layer. Ciphertext looks random to any compressor, and because new EBS volumes are encrypted by default, a typical production snapshot chain gets no compression benefit at all.
Eon's vault reads the decrypted volume, deduplicates and compresses the plaintext, then encrypts the packed result. That ordering is where Eon customers' 30–50% storage reduction comes from. NETGEAR cut snapshot storage costs by 35% after moving to Eon's vault, and recovery of a 10 TB SQL Server database dropped from 24 hours to 3.
Where AWS snapshot backup leaves recovery exposed
A snapshot schedule can be complete and still leave a gap between what exists and what can actually recover. The gaps below are baked into the artifact's design, so tuning the schedule alone will not close them.
Restore time and lazy loading
A volume created from a snapshot becomes available in seconds, and that availability misleads. Blocks are downloaded from S3 on first read, so a database on the new volume runs slow until every block it touches has loaded.
Fast Snapshot Restore hands you a fully initialized volume, but only from snapshots you flagged in advance, only up to 16 TiB, and only while a per-zone credit bucket has credits left.
Provisioned Rate streams blocks at 100 to 300 MiB/s, so a 10 TB snapshot still needs over nine hours at the top rate. Neither fix changes the unit of restore. Both hydrate the whole volume when you need one directory.
Single-file recovery paths
Native snapshots are volume-level artifacts. The supported route to one file is a full volume restore, then a manual copy. You build the volume, attach it on a spare device, and copy the file home. One RDS table means one new instance.
AWS Backup added search and item-level recovery for EBS snapshots in December 2024. The snapshot must be indexed in advance, a job caps at five items, and the output lands in S3, never back on the volume.
That design suits a handful of known files and has nothing to offer a corrupted schema or a few thousand deleted records. Record, table, and file restores without a volume rebuild are what Eon's granular recovery exists for.
Shared blast radius with the source
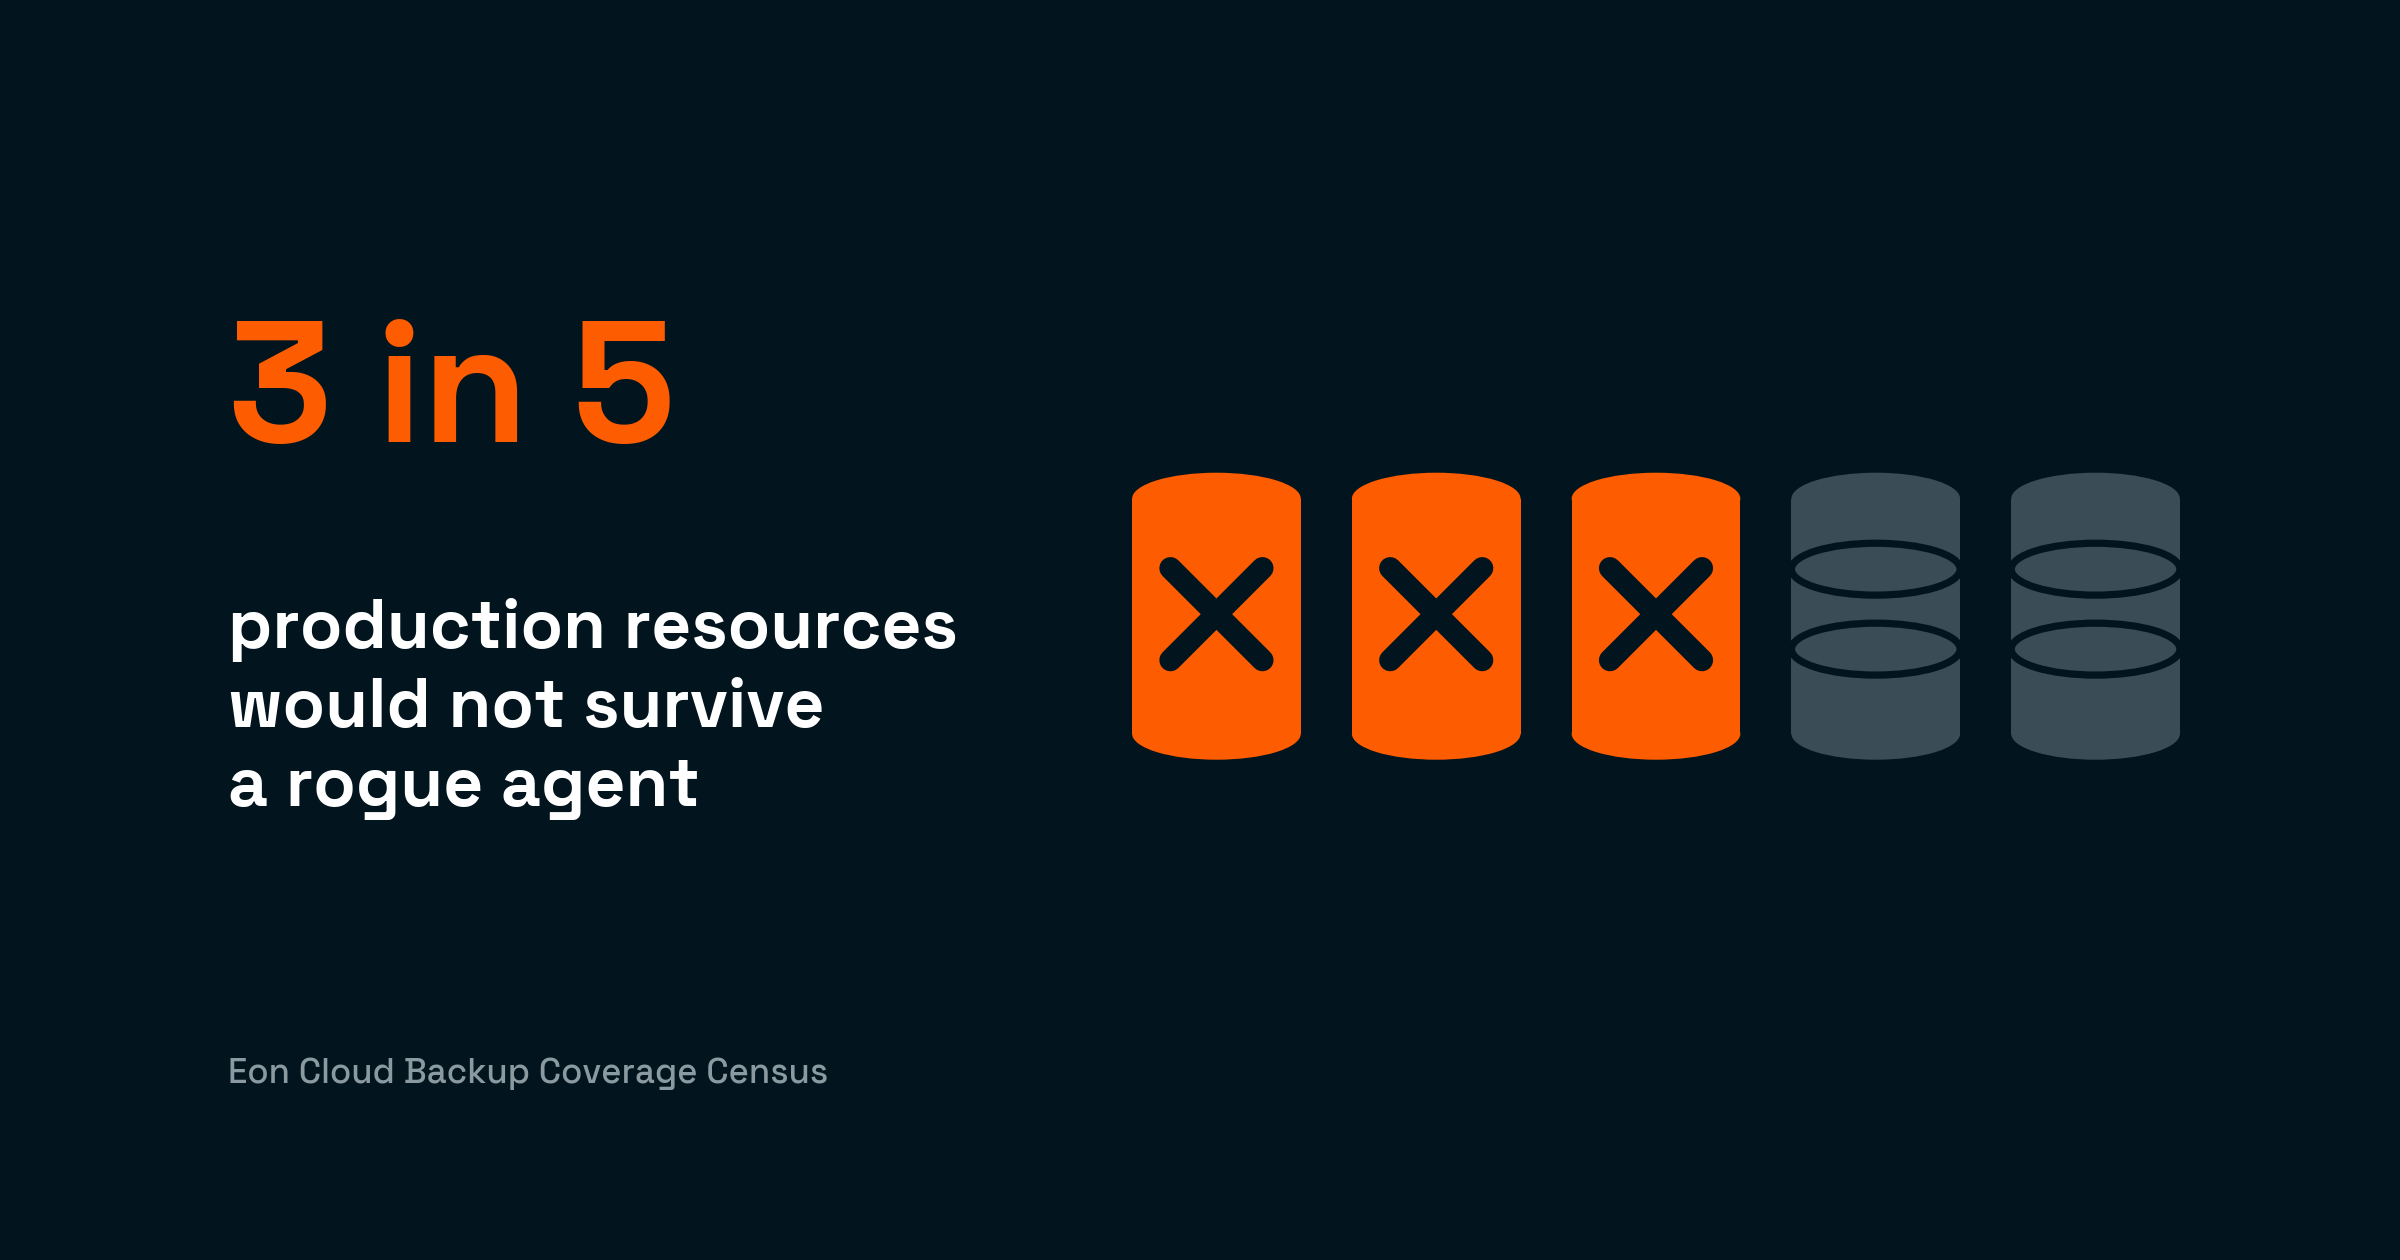
The worst AWS incidents follow one script. An intruder with admin credentials encrypts or deletes production, then deletes the snapshots in the same account. Every one we have investigated had working schedules until they were erased.
The fix is to copy the source account that cannot be touched. Eon holds backups in an immutable, logically air-gapped vault in a separate account, so a compromised production credential reaches nothing in it.
Retention ceilings and quotas
RDS automated backups run for a maximum of 35 days. Anything kept longer becomes a manual snapshot, a full copy that never expires on its own and counts against a quota of 100 per region.
Default retention depends on how you created the instance. The console sets seven days, while the API and CLI set one. Any database provisioned through infrastructure-as-code without an explicit value has a single day of history.
AWS snapshot backup best practices
These practices close most of the gaps in the native model. None changes the shape of the artifact, but together they turn a snapshot schedule into a recovery plan you can defend.
1. Separate data volumes from operating system volumes
Give database files, logs, and the operating system separate EBS volumes, so each gets a policy sized to its change rate and restores alone. Hourly data snapshots plus weekly root snapshots cost a fraction of one instance-wide policy.
2. Automate with DLM or AWS Backup and not with scripts
Cron jobs and Lambda functions calling create-snapshot drift the moment an instance launches without the right tag. DLM covers creation, retention, cross-region copy, and FSR for EBS. AWS Backup adds RDS, EFS, and DynamoDB.
Either one enforces the schedule. Neither notices the resource that was never tagged. Eon's Cloud Backup Posture Management (CBPM) closes that gap by classifying resources on creation and attaching policy without tags.
3. Quiesce databases before the snapshot runs
For any volume holding a database, attach pre-snapshot and post-snapshot scripts to the DLM policy, or use VSS on Windows. A crash-consistent copy of a busy cluster is a coin flip, and the restore is the wrong moment to find out.
4. Lock retention-critical snapshots in compliance mode
Snapshot Lock has two modes. A governance lock is a guardrail that an administrator with the right IAM permission can remove. A compliance lock turns permanent after a cooling-off window of at most 72 hours and can only be lengthened.
Use governance for operational snapshots and compliance for the copies your auditors will ask about.
aws ec2 lock-snapshot --snapshot-id snap-0abc123 \

  --lock-mode compliance --cool-off-period 24 --lock-duration 365
5. Copy cross-account on a customer-managed KMS key
AWS will not let a snapshot encrypted with the default aws/ebs key leave the account. If your volumes use that key, the cross-account copy job you set up last quarter has been erroring out the whole time.
Re-encrypt onto a customer-managed key, grant the destination account the KMS actions it needs, and confirm a copy completes before you rely on it.
6. Turn on Recycle Bin retention rules
A region-level Recycle Bin rule holds deleted snapshots for up to 365 days and can be locked with a 7-to-30-day unlock delay. A compromised principal that deletes your snapshots and tries to empty the bin still has to wait it out.
7. Archive only when the 90-day math works
Archive a snapshot only when it is a monthly or quarterly copy you keep for months and restore rarely. Archived snapshots cannot create a volume until restored to standard, so keep them out of any path with an RTO under a day.
8. Test restores and measure time to full performance
A restore drill that stops at "volume available" tests nothing. Start the application on the restored volume, run its production queries, and time when latency drops to baseline. EBS reports a volume initialization status for that moment.
If the measured time beats your RTO, the snapshot is a recovery point. If it does not, you have a copy.
Where native snapshots are no longer enough
Native snapshots serve well for short-retention, same-account rollback. A dev fleet you can rebuild, a stateless tier behind an AMI pipeline, and a database you roll back within a week all fit inside DLM or AWS Backup.
The model strains at three points. Long retention multiplies full copies past the 35-day RDS line and across regions. Ransomware multiplies the value of a copy outside the blast radius. Multi-account scale multiplies untagged resources.
A fourth point is newer. Backup data has become a dataset in its own right, and organizations running analytics and AI against production because their backups are unreachable are paying twice for the same data.
A native snapshot stays dark until it becomes a running instance. Eon holds database backups as Parquet, Iceberg, and Delta Lake, so the copy that serves a restore also serves zero-ETL queries in Snowflake, Databricks, BigQuery, and Athena.
The bottom line on AWS snapshot backup
AWS snapshot backup gives you cheap, durable, incremental copies, and the best practices above close most of the gaps in the native model. What they cannot change is the shape of the artifact.
A snapshot restores as a whole volume, lives in the account that made it, and stays dark until you rebuild something around it.
If a credential in your production account was used to delete every snapshot tonight, what would you restore from tomorrow? Book a demo and see how Eon delivers backup that actually recovers, outside your account and without the volume rebuild.
Frequently asked questions
Is an AWS snapshot a full backup?
An AWS snapshot is a full, restorable point-in-time copy that is stored incrementally. Any single snapshot can rebuild the whole volume because it references blocks shared with earlier ones. It is crash-consistent by default.
How is an AWS snapshot different from AWS Backup?
An AWS snapshot is the artifact, the point-in-time block-level copy stored in S3. AWS Backup is the orchestration layer that creates, retains, copies, and governs those snapshots (plus RDS, EFS, DynamoDB backups) from one policy. You can take snapshots without AWS Backup, but not the other way around.
How long does it take to restore an EBS snapshot?
The volume is available within seconds, but full performance arrives only after every block has loaded from S3. Without Fast Snapshot Restore or a Provisioned Rate, a large volume runs degraded for hours.
Can you restore a single file from an EBS snapshot?
Through the snapshot itself, no. You create a volume, attach it to an instance, and copy the file out. AWS Backup can pull individual files from an indexed EBS snapshot, five per job, into an S3 bucket.
What is the difference between an AWS snapshot and an AMI?
An AWS snapshot captures the blocks of one EBS volume and restores as a volume you attach to an instance. An AMI wraps one or more snapshots with launch permissions and a block device mapping, and restores by launching a new instance.
How long can Amazon RDS keep automated backups?
RDS automated backups support a retention period of 0 to 35 days, where 0 disables them. To keep a backup longer, copy it to a manual snapshot, which persists until deleted and counts toward the quota of 100 per region.