

At 2 p.m., a coding agent with valid production credentials runs a migration that truncates the orders table. Nothing else breaks, and every other table keeps taking good writes for the next 40 minutes (the agent did exactly what it was told, which is the whole problem).
Native point-in-time recovery would hand you a new instance from 1:59 p.m., which rewinds every one of those healthy tables along with the broken one. That's why I match RDS backup solutions to the incident they survive, and the eight picks below cover everything from one bad table to a lost Region.
If you just want the shortlist:
Eon is the best RDS backup solution when one table goes bad and the rest of the database is fine, because it restores just the damaged table or the rows a SQL query matches while every later good write stays put.
Amazon RDS automated backups stay the base layer for short rollbacks inside 35 days, with manual snapshots and cross-Region automated backups for longer or farther copies. AWS Backup covers account compromise through cross-account copies and Vault Lock.
Rubrik suits security-led investigations across a broader estate, N2WS (now N2W) drives Regional DR inside AWS, and Commvault (Clumio) keeps long-retention compliance copies. Veeam fits VM-heavy shops, and Druva suits SaaS-first teams adding RDS.
Five incidents an RDS backup plan has to survive
Most RDS backup plans get written for one incident (usually "the database disappeared") and then get tested by a different one. These are the five I plan around.
One table goes bad while the rest stays healthy. A migration, a bad deploy, or an agent with real permissions damages a single table. Native restores always build a new instance, so the fix turns into a copy-the-rows-back job under pressure.
A mistake you catch a few days later. Automated backups let you restore to a specific point in time inside the retention window, which caps at 35 days. That window only helps if somebody set it above the default.
Someone takes over the production account. RDS snapshots live in the same account as production unless you copy them out, and none of the RDS backup pages I checked describe a native lock for snapshots.
A Region goes down. You need copies somewhere else, and cross-Region automated backups aren't supported for Multi-AZ DB clusters, so the design depends on how you deployed.
An auditor asks for last year's records. Anything past 35 days means manual snapshots, AWS Backup, or a third-party vault, and each one handles restore scope differently.
1. Eon, when one table goes bad and the rest of the database is fine
This is the incident from my opener, and it's where the platform is strongest. It's cloud data protection and recovery that connects through a single read-only role, with no agents, appliances, or clusters to run.
Coverage spans Amazon RDS on MySQL, PostgreSQL, MariaDB, SQL Server, and Oracle (19c and 21c), plus Amazon Aurora and self-managed MySQL, PostgreSQL, and SQL Server on EC2. (The founding team built CloudEndure, which AWS later acquired, so the AWS fluency comes from experience.)
It works alongside your RDS automated backups. The company now manages AWS-native PITR for RDS and Aurora, setting retention centrally across accounts and Regions while recovery points stay in your own account.
Its recommended setup is a dual policy, such as 7-day PITR for fast rollbacks plus its own snapshot policy for long retention, compliance, and database exploration.
Those snapshots land in an immutable, logically air-gapped vault in a dedicated account, and time-bound access keeps a stolen production key away from recovery data.
Restore verification is the part I'd test first: it fingerprints every table, restores the backup to a temporary instance, and compares the fingerprints. Native RDS backup jobs report success without checking that the data came back intact.
Its ransomware detection (add-on) correlates multiple independent signals (such as row-count drops, schema changes, and ransom notes) into one weighted score, and it also flags damage from rogue AI agents. Detection for databases is in early access.
Pricing is usage-based, billed per GB per month on protected storage, with no tier ladder and flexible spending commitments, and the company claims up to 50% lower cost through global deduplication.
How it handles the incident: You restore the instance, a database, one table, or only the rows a SQL query matches, so rolling back the exact records the agent hit takes minutes.
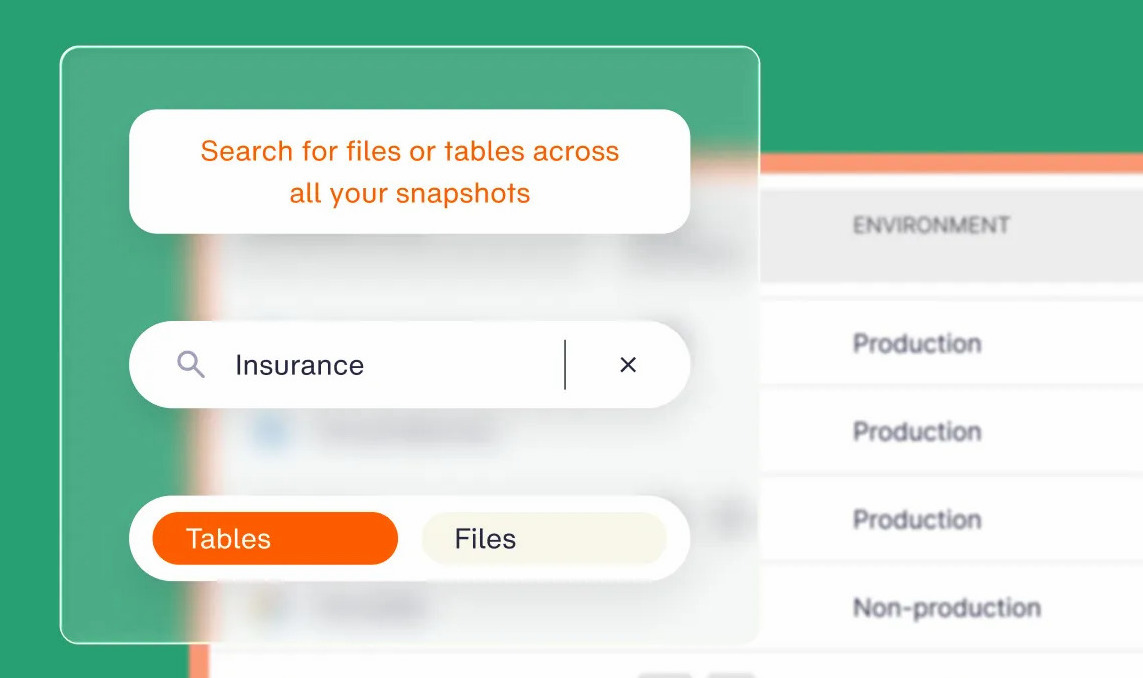
Global Search finds those records across backups in seconds, and Database Explorer runs SQL against a backed-up snapshot without a restore, so you can confirm the damage before touching production.
Limit: There's no public list price, and the reference list is shorter than the incumbents can offer. On-prem support is limited, so an estate that's still mostly on-prem needs a separate tool for the data center.
2. Amazon RDS automated backups, when you need a short rollback inside the retention window
Keep these on. RDS takes a storage volume snapshot of the whole instance and uploads transaction logs to Amazon S3 every five minutes, so you can restore to a specific point in time inside a retention window of up to 35 days.
The defaults trip people up: one day through the API or CLI, seven through the console. (Go check yours. I'll wait.)
Manual snapshots handle anything longer, because they aren't subject to the retention period and don't expire, although the default quota is 100 per Region. Cross-Region automated backups replicate both snapshots and transaction logs into another Region (the default quota is 20 per account).
On Aurora, backups are continuous and can't be disabled, and the latest restorable time is typically within 5 minutes of the current time. Aurora MySQL also gets Backtrack, which rewinds a cluster in place within a 72-hour window.
As of October 2026, backup storage is free up to 100% of your total database storage in a Region. Beyond that, RDS charges $0.095 per GiB-month in US East (N. Virginia), and Aurora's extra backup storage runs $0.021 per GB-month.
How it handles the incident: Point-in-time recovery creates a new DB instance without modifying the source, which is the right move when a bad deploy went out an hour ago and you'd happily rewind everything. On Aurora MySQL clusters created with Backtrack enabled, Backtrack rewinds in minutes.
Limit: There's no table or row restore, and Backtrack is cluster-wide, so a one-table incident means restoring a new instance and copying rows back by hand. Restored volumes also load blocks from S3 in the background, so performance can lag until initialization completes.
3. AWS Backup, when someone gets hold of the production account
AWS Backup is the native policy layer I'd want in place before an account compromise, because it manages backup policy for multiple accounts from a single management account in AWS Organizations.
For RDS, it creates manual DB snapshots through the RDS API, and continuous backup restores within one second of precision, going back up to 35 days.
The compromise answer is cross-account copies plus Vault Lock. Cross-account copies need both accounts in the same AWS Organization, and a vault under compliance-mode Vault Lock becomes immutable once its grace time (at least 72 hours) ends, so nobody, AWS included, can change or delete it.
Governance mode is softer, since users with enough IAM permissions can remove the lock. Logically air-gapped vaults accept Aurora clusters but leave out RDS DB instances, so an RDS instance gets its isolation from a Vault Lock vault in a second account.
Restore testing runs scheduled restores against the latest or a random recovery point and deletes the test resources afterward, and Backup Audit Manager checks your policies against controls you define.
As of October 2026, you pay for storage, cross-Region transfer, restores, and backup evaluations, with no minimum fee. RDS snapshots bill at $0.095 per GB-month in us-east-1, restores of RDS snapshots are free, and Vault Lock costs nothing extra.
How it handles the incident: An attacker holding production credentials can't reach compliance-mode copies in a separate account, and Backup Audit Manager reports whether your backups meet the controls you define.
Limit: Copies to another account or Region arrive as snapshots, so the PITR window stays in the source account, and continuous backup doesn't cover Multi-AZ DB clusters.
There's no item-level restore for RDS or Aurora, and once AWS Backup takes over continuous backup, you can't change retention from the RDS console or APIs.
4. Rubrik, when security is running an investigation across a broader estate
Rubrik describes itself as the Security and AI Operations Company, and it fits when the RDS incident is one thread in a wider investigation that also touches on-prem and multi-cloud systems. Rubrik Security Cloud applies SLA policies to RDS instances across accounts and Regions from a central UI.
Setup runs a CloudFormation template that creates a cross-account IAM role without long-lived keys. Its RDS data sheet lists MySQL, MS SQL, Oracle, MariaDB, and PostgreSQL, and Rubrik protects transaction logs and says it can restore RDS instances to an exact point in time within minutes.
You pick a deployment model. In the customer-hosted model, Rubrik's compute runs in your own AWS account and your team owns networking and IAM, while Rubrik Managed Cloud Protection runs compute and vault in Rubrik's environment with Object Lock on by default.
As of October 2026, there's no public price list, and pricing is quote-based through sales.
How it handles the incident: The security team gets one policy engine and console across on-prem, multi-cloud, and RDS, and the Managed model keeps immutable copies outside your AWS organization while the investigation runs.
Limit: Rubrik's public RDS pages don't describe threat scanning of RDS backups, and file-based scanning reads storage files, which a managed database like RDS never exposes.
Rubrik's original RDS protection rides on native snapshots, so the manual snapshot quota applies to it, and Rubrik's own blog says the Managed model "moves data outside your AWS organization by design."
5. N2WS (now N2W), when a whole Region goes dark
N2W, formerly N2WS, is the tool I'd look at when the incident on the whiteboard is a Regional outage. It's a Linux-based virtual appliance you launch from an AMI in your own account, and it uses AWS APIs to manage snapshots of RDS instances and clusters, plus Aurora (including Aurora Serverless).
Its supported-services table marks RDS for both cross-Region DR and cross-account DR, and schedules can run every 15 minutes.
Two documented constraints shape the plan: AWS can't share snapshots encrypted with the default KMS key across accounts, and N2W's docs say its cross-account RDS copies land in the DR account in the original Region.
For a second layer, N2W can export RDS to an S3 repository in Parquet format, which S3 Object Lock can protect, though that path covers only MySQL and PostgreSQL and excludes Aurora.
As of October 2026, N2W is a flat monthly subscription based on instance count. Standard costs $249 a month for 20 instances or VMs and three accounts, Advanced and Enterprise are quoted, and every plan has a 30-day free trial.
(A bill that ignores data growth is a rare treat in this category.)
How it handles the incident: Cross-Region DR copies and orchestrated recovery run from a server you own, so you can plan and rehearse a Regional failover ahead of time.
Limit: You run and patch the N2W server yourself, and upgrades ship as a new AMI that wipes OS changes. RDS backups stay native snapshots unless you add the S3 copy, and an Aurora restore fails if the original cluster ID still exists unless you change it.
6. Commvault (Clumio), when compliance needs long-term copies
Clumio, a Commvault company, is the long-retention pick here. It unifies in-account automated snapshots and logically air-gapped backups of RDS instances and Aurora clusters under one policy, and it splits them into two tiers.
SecureVault Standard handles retention under three months, and SecureVault Archive keeps logical copies longer. Archive is where compliance teams lean in, because you can retrieve individual records straight from the backup after a thaw period of up to 48 hours.
Supported engines include Aurora MySQL, Aurora PostgreSQL, MariaDB, RDS for MySQL, RDS for PostgreSQL, RDS for SQL Server, and RDS for Oracle SE2 and Enterprise Edition. Commvault Cloud also protects RDS across accounts and Regions, with Amazon RDS for Oracle on its supported list.
As of October 2026, RDS Archive lists at $0.01 per GiB-month, with full backups every seven days and $0.025 per GiB restored, plus an early deletion fee if you keep data under 12 months. Standard runs $0.14 per GiB-month with incremental backups every four hours and $0 restores (data transfer out fees still apply).
How it handles the incident: Old records come back from a logically air-gapped copy without rebuilding a full database, which suits an audit request that only needs a handful of rows.
Limit: Archive has no full-database restore and starts after 48 hours, and logically air-gapped backups have a minimum RPO of 4 hours. Archive and record retrieval aren't supported on Oracle Enterprise editions or Aurora Serverless, and Clumio uses RDS manual snapshots, so AWS quotas apply.
7. Veeam, when VMs run the estate and RDS rides along
If your team already lives in Veeam Backup & Replication, the AWS side now arrives as the Veeam Plug-in for AWS in version 13. It adds backup appliances to the infrastructure you already run, so the RDS slice doesn't require learning a second tool.
It works two ways: cloud-native snapshots of RDS instances and Aurora clusters, replicated to any Region in any account, or image-level backups of SQL Server and PostgreSQL (versions 12 through 17) stored in S3.
Image-level jobs deploy a worker instance in the production account and remove it when the session ends.
That image-level path is the draw, because it supports database-level restore for SQL Server and PostgreSQL. Veeam Data Cloud for AWS is the SaaS route, though Veeam's US page doesn't break out which AWS services the SaaS option covers or what it costs.
As of October 2026, the plug-in is licensed per protected instance (each RDS resource counts as one), and the paid edition runs on a subscription Veeam Universal License.
A Free edition protects up to 10 instances on standalone appliances, minus image-level PostgreSQL backups, and the US page for Veeam Data Cloud for AWS lists no price.
How it handles the incident: A VM-first team protects RDS with the same Backup & Replication server, licensing, and people it already has, and restores a single SQL Server or PostgreSQL database from image-level backups.
Limit: Image-level backups cover SQL Server and PostgreSQL only, so every other engine, Aurora included, gets snapshots only. Each job also needs network plumbing: VPC DNS resolution on, a public IPv4 subnet with an internet gateway or private endpoints, and two temporary security groups.
AWS, Azure, and Google Cloud protection also come as separate plug-ins, each with its own appliances.
8. Druva, when a SaaS-first team adds RDS to the list
Druva now brands its platform The Resilience Cloud, and it grew up protecting endpoints and SaaS apps. It fits teams that want the AWS side delivered the same way, as a service with no infrastructure to run.
For RDS it has two layers. CloudRanger orchestrates snapshots, cross-Region and cross-account copies, DR plans, and scheduling, while Druva's SaaS vault option stores backups decoupled from your AWS Organization in Druva's cloud, uses AWS KMS, and needs no agents.
On its Enterprise and Elite plans, Druva says Data Lock prevents alterations and deletions, and it claims no egress fee for cross-Region copies.
Check cluster support against your estate, because Druva's own AWS support matrix (dated October 2025) says RDS Cluster backup and restore is not currently supported, while its newer SaaS vault guide (updated May 2026) says RDS clusters are protected.
As of October 2026, Druva publishes no dollar figures. The public cloud plans (Business, Enterprise, and Elite, plus a free trial) are priced per TB per month after deduplication.
How it handles the incident: A team that already runs Druva for endpoints and SaaS apps adds RDS without standing up servers, and the vault copy sits outside its AWS Organization.
Limit: The vault copy isn't supported for RDS instances encrypted with AWS managed keys, and backups fail when manual snapshots exceed the AWS quota (100 per Region by default).
Druva documents no table or record-level restore for RDS, and storing backups in Druva's cloud puts recovery data inside the vendor's boundary, which is an architecture tradeoff to weigh.
Match the tool to the incident
- One table damaged, everything else healthy: pick a tool with table and row restore, and keep native PITR running underneath.
- A rollback within days: Amazon RDS automated backups, with retention set well above the one-day API default.
- Compromised production credentials: AWS Backup cross-account copies into a compliance-mode Vault Lock.
- A security investigation that spans on-prem and cloud: Rubrik, with its RDS limits in mind.
- A Regional outage: N2W's cross-Region DR, or cross-Region automated backups if you don't run Multi-AZ DB clusters.
- Records kept long term: Clumio's Archive tier, as long as a 48-hour thaw is acceptable.
- A VM-heavy estate or a SaaS-first team: Veeam or Druva, respectively, so RDS joins the tool you already operate.
Make the 2 p.m. restore boring
The incident you'll most likely face is small: a single table, a valid credential, and a write that looked fine until a customer called.
So run that exact drill: damage one table in a staging copy, restore only what broke, and time it. If the only restore your team has ever practiced is a full instance into a sandbox, you haven't tested the incident you're most likely to have.
Frequently asked questions
What's the fastest way to recover one damaged table in Amazon RDS?
Restore only that table, or just the rows a SQL query matches, from a backup that supports granular restore, which Eon does without rebuilding the instance. Native RDS restores always create a new instance, so without that you're copying rows back by hand.
Does Multi-AZ count as an RDS backup?
No. Multi-AZ gives you a standby, and your recovery points still come from automated backups and snapshots; on MariaDB, MySQL, Oracle, and PostgreSQL Multi-AZ instances, RDS simply takes those backups from the standby so the primary isn't suspended.
Can ransomware reach RDS snapshots?
Yes, if the attacker holds credentials in the production account, because RDS snapshots live there unless you copy them out. Copy them to a separate account into an AWS Backup vault under compliance-mode Vault Lock, which nobody, AWS included, can change or delete once the grace time ends.