Eon Yukon vs. Amazon EMR
Why teams move ingestion and table upkeep off EMR clusters
No clusters to move data
Eon takes over the Spark and Flink streaming jobs, merge query jobs and compaction jobs that keep EMR clusters running, and lands clean tables in one pass.
Pay per query, nothing when idle
Existing Spark batch jobs can connect over Spark Connect and run serverless, so you don't size a cluster for the peak or pay for warm workers while they wait. RDD-based and custom-JVM jobs, and GPU training, stay on Spark.
Fresh, open tables on S3
Kafka and S3 data land as Apache Iceberg tables in S3 and AWS Glue within seconds, where Athena, Redshift, Snowflake or Databricks read them.
Eon vs. Amazon EMR at a glance

Data freshness
Query-ready data within seconds.
As fresh as the Spark Structured Streaming or Flink job you build. Iceberg advises Spark triggers of at least one minute.
Data preparation & maintenance
Event-level data lands ready to query, with optional updates, deduplication and aggregates. Table maintenance is built in.
Upserts and dedup are Spark or Flink code you write. Automatic Iceberg compaction comes from AWS Glue table optimizers, set up separately.
Pipeline complexity
Eon Stream: one managed pipeline produces the tables you choose in one pass, with no separate processing or maintenance jobs.
A streaming job, merge query logic, a maintenance schedule and a cluster or application for each.
Context for AI agents
Eon Context: built-in table descriptions, statistics and change history help agents understand and query the data.
AI-suggested descriptions in SageMaker Catalog, generated once and reviewed by hand. No per-commit statistics, value-matched joins or change log.
Open formats & interoperability
Iceberg tables, readable by compatible engines.
Runs Iceberg, Delta Lake and Hudi through Spark, Flink, Hive and Trino.
Querying & compute management
Eon Query: serverless SQL and Spark Connect, billed per query with no idle compute cost.
EMR on EC2 clusters, EMR on EKS, or EMR Serverless, where warm workers are billed even while idle.
Real-time application serving
Eon Realtime: current values, looked up by key in under 1 ms through Redis-compatible and HTTP APIs.
No serving layer. Results land in a sink, and apps read from a separate cache.
Real-time aggregations
Summaries update alongside event-level data, written to tables and served live, with no state for your team to manage.
Stateful windows in Spark or Flink jobs you write and operate.
Operational overhead
Fully managed by Eon, with no tuning required. Dedicated deployment in your region or BYOC.
Your team picks instances, tunes managed scaling and auto-termination, and runs on-call for the jobs.
Compute efficiency
At 1M events/s: 35 vCPU for ingest and 63 with compaction, 4× Spark's compute efficiency.
135 vCPU for Spark Structured Streaming, which EMR runs (about 7,400 rows/s per vCPU), and as much again to compact it.
How Eon Yukon compares with Amazon EMR
Ingest and table upkeep without a cluster
Many of the EMR clusters that run around the clock are there to land Kafka and S3 data in tables, merge updates, and compact the small files that streaming leaves behind.
On EMR, each of those is a Spark or Flink job your team writes, sizes and schedules. EMR Serverless streaming jobs run continuously with no execution timeout, and Iceberg compaction comes from separate AWS Glue table optimizers.
Eon Stream does all of it in one pass: deduplication, upserts and deletes on compound keys, transforms, sorting and compaction, committed together to Iceberg in S3, with tables that stay right-sized as they grow.
In Eon's tests, Eon sorts the same hourly batch about 13x faster than Spark, and in a neutral benchmark on public data, Spark Structured Streaming missed a one-minute freshness target at every rate.
Spark jobs, serverless and per query
Teams size batch ETL clusters for the nightly peak and keep Spark, Trino or Presto clusters up for ad-hoc questions.
EMR on EC2 bills per second with a one-minute minimum and an EMR charge on top of each instance, and auto-termination waits an hour of idle time by default. EMR Serverless removes the cluster, but AWS bills pre-initialized workers, which start jobs in seconds, even while the application is idle.
Eon Query bills per query, with nothing to pay when idle, and existing PySpark and SQL jobs can connect over Spark Connect, serverless. Eon Query answers counts, ranges and distinct values from statistics written at ingest. RDD-based and custom-JVM jobs, and GPU training, stay on Spark.
Context agents read before they query
Agents need to know what a table means before they can answer from it.
EMR's AI agent helps engineers troubleshoot Spark jobs, which is a different job from describing the data in the tables to the agents that query them.
Eon Context writes a description of every table with each commit: grain, column meaning, distributions, joins found by matching values, and what changed. Agents read it over MCP, so one call replaces the exploratory queries.

Open tables every AWS engine reads
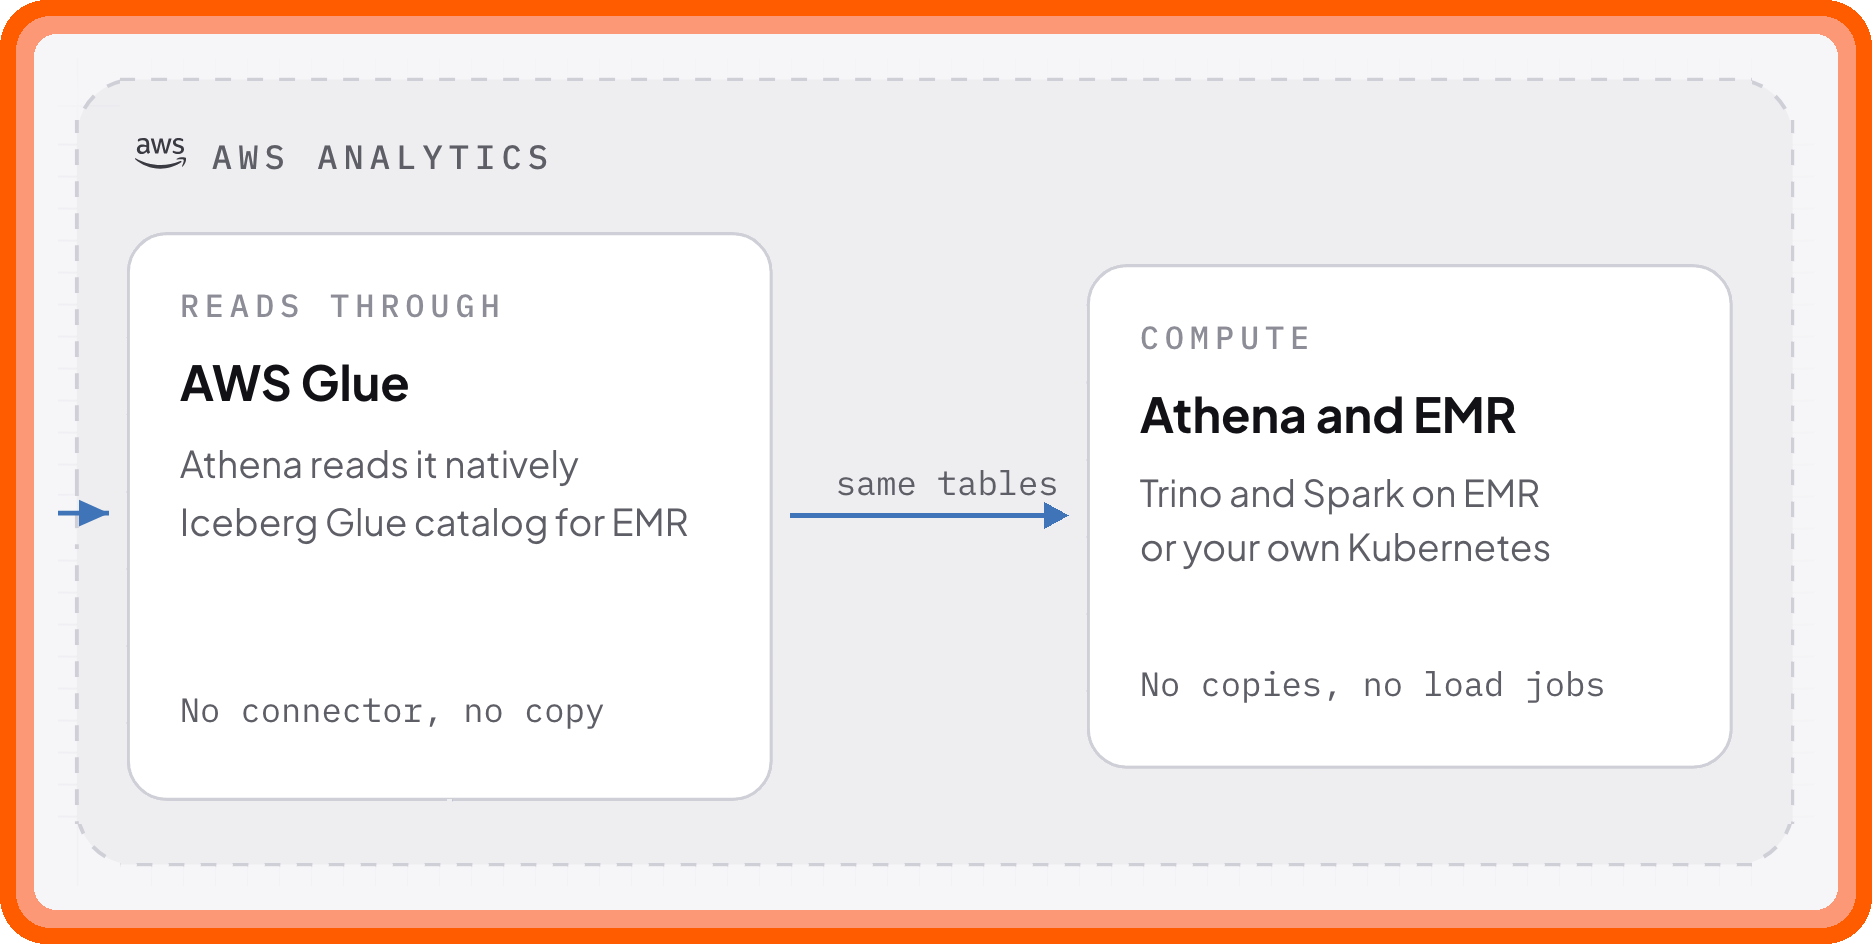
Teams on AWS already query the lake from Athena, Redshift, EMR and third-party engines, and don't want another copy.
EMR reads and writes open formats well, and your team owns the jobs that keep those tables fresh and compacted.
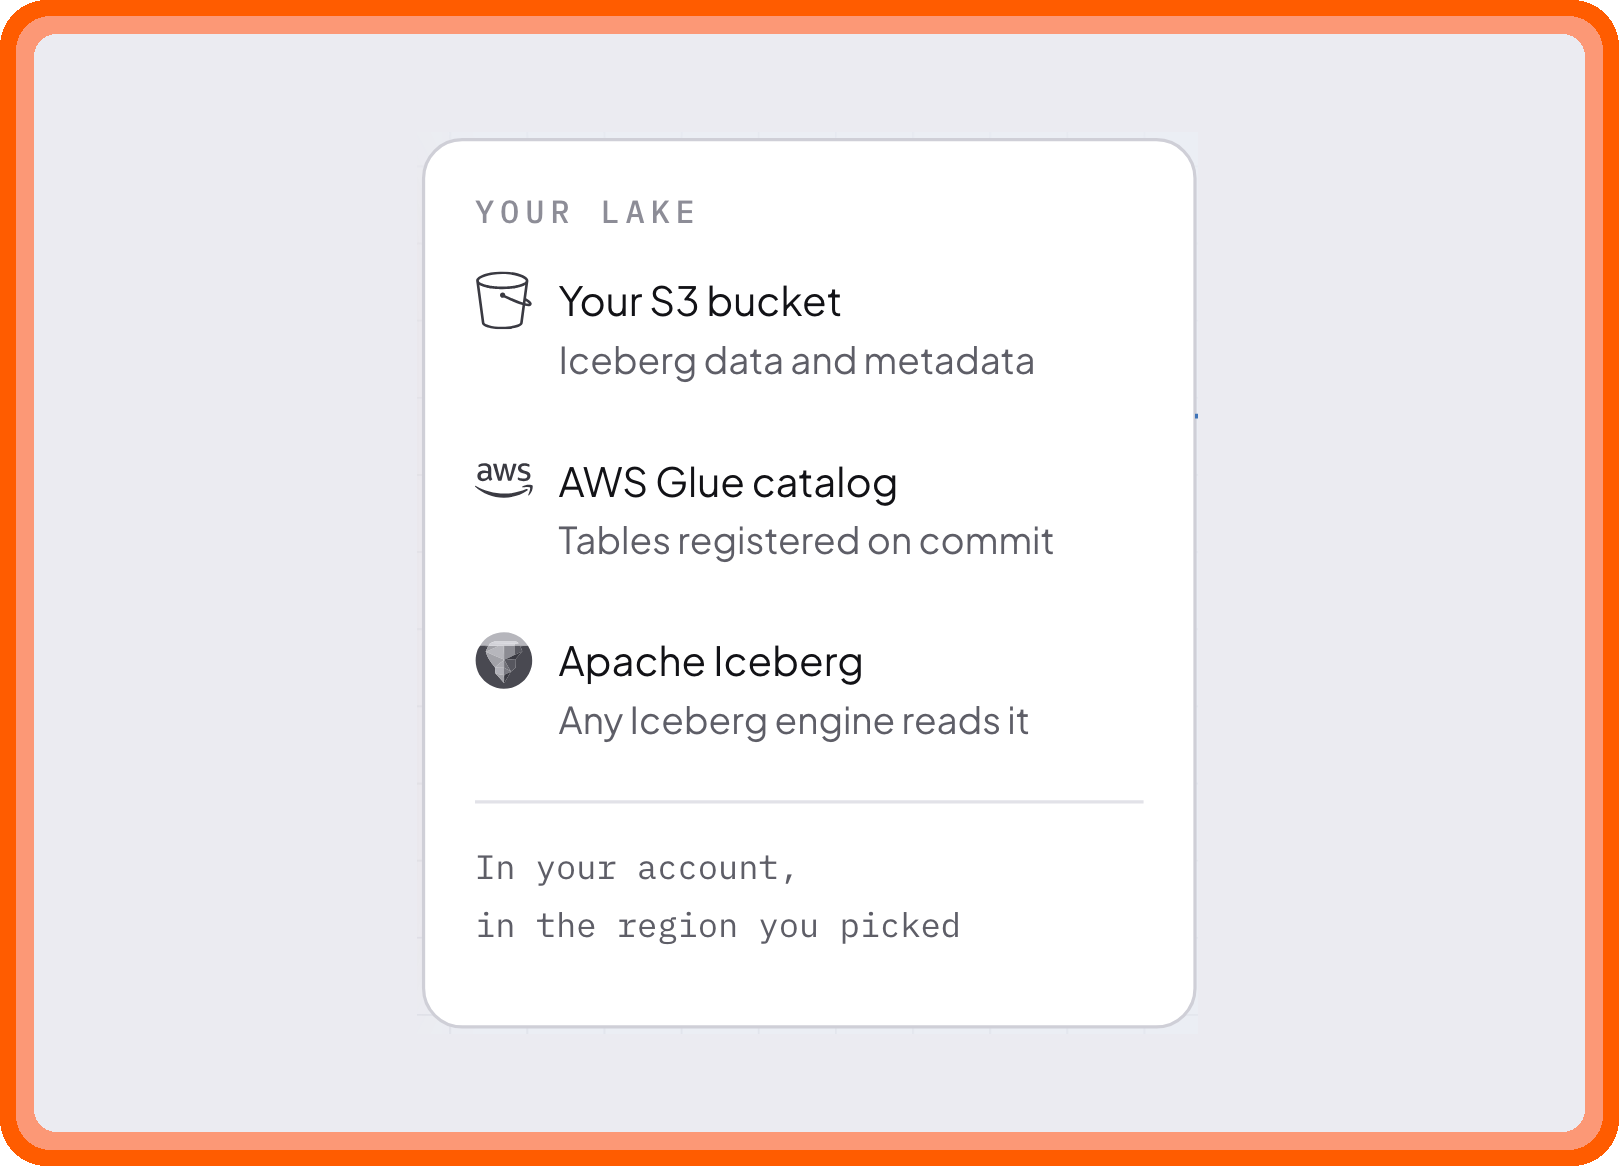
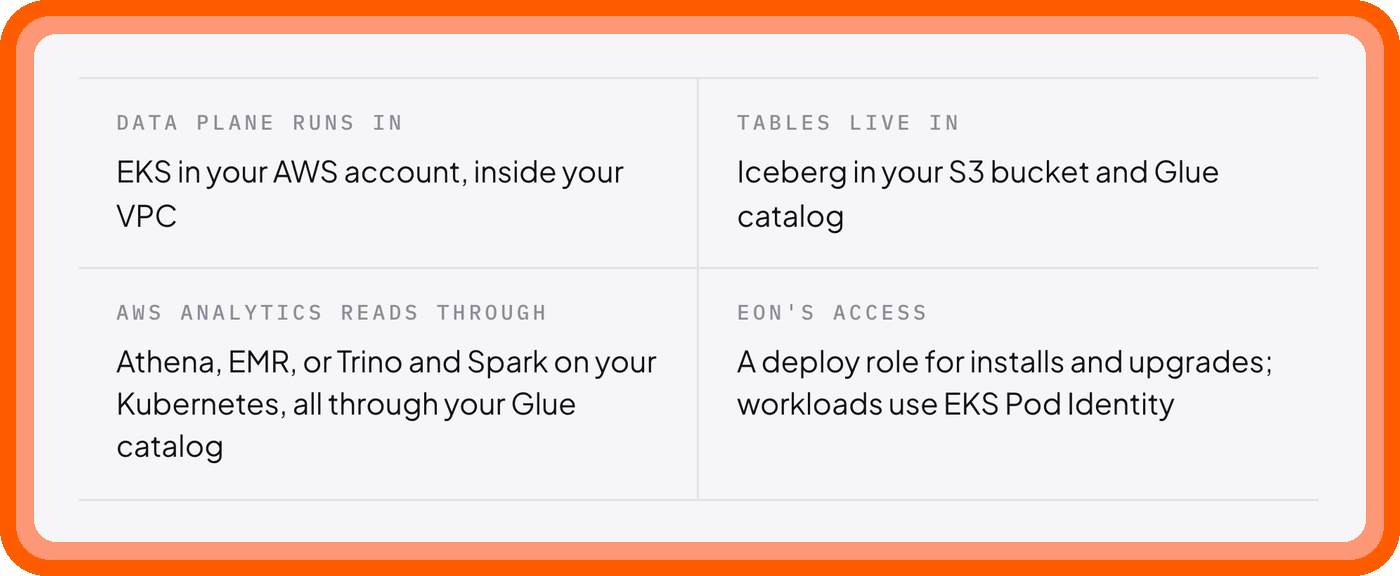
Eon Stream writes Apache Iceberg tables to S3 and registers them in AWS Glue on commit. Athena, Trino, Spark, Snowflake and Databricks read them in place, and EMR can keep running the jobs that need it, such as RDD-based jobs and GPU training. With Eon Data Protection, your database backups land as Iceberg tables in the same lake, queryable with no pipeline (managed deployments).
How EMR pipeline costs compound
Streaming ingest
Included.
A long-running Spark or Flink job, billed while it runs.
Upserts and dedup
Included, applied as data lands.
Merge query jobs on the same clusters.
Compaction and cleanup
Included, continuous.
Spark maintenance jobs or AWS Glue table optimizers.
Batch ETL and queries
Per query, nothing to pay when idle. Spark jobs can connect over Spark Connect.
Clusters sized for the peak, or warm workers billed while idle.
Where the difference shows up most:
High-volume streams
compute grows with event rate. Eon uses 4× to 7× less compute than Spark and Flink to ingest and compact the same stream.
Idle time
clusters and warm workers kept up for ad-hoc and agent queries cost money between questions. Eon bills only for the queries it runs.
More tables
each new stream on EMR brings its own job and maintenance schedule. With Eon, cost follows data volume rather than the number of jobs.

See how Eon works in your environment
Bring a stream you process on EMR today and we will show you that data landing in Eon Yukon tables, with freshness and compute compared side by side.