AI-Ready Object Storage, Multi-Region by Design
AI agents and applications can now reach back into data that sat untouched for years. Eon keeps billions of objects resilient across two regions you choose and serves everyday reads locally, with no rehydration job. Each copy is tiered by how it’s actually used, for up to 35% lower TCO.
Storage tiering wasn't built for how AI reads data
Object storage tiering assumes data cools with age. AI agents and assistants break that assumption, searching years of history and pulling old records back in as context for a single question. Across billions of small objects, that gets expensive in two ways. Cloud geo-redundancy adds a premium on every byte, cross-location read billing and replication charges on every write. Age-based tiering adds retrieval fees and minimum storage durations on cold data, while small objects never leave the Standard tier.
An index, not just a bucket
Every object written through Eon is recorded in a metadata index that sits beside the data. Listing and lookups are answered from that index rather than from the bucket, which is what keeps them fast and inexpensive when the namespace runs to billions of objects. It is also the same foundation Eon’s discovery, sensitive-data classification, and search are built on across protected AWS, Azure, and GCS estates.
How Eon cuts multi-region cost for billions of objects and constant reads
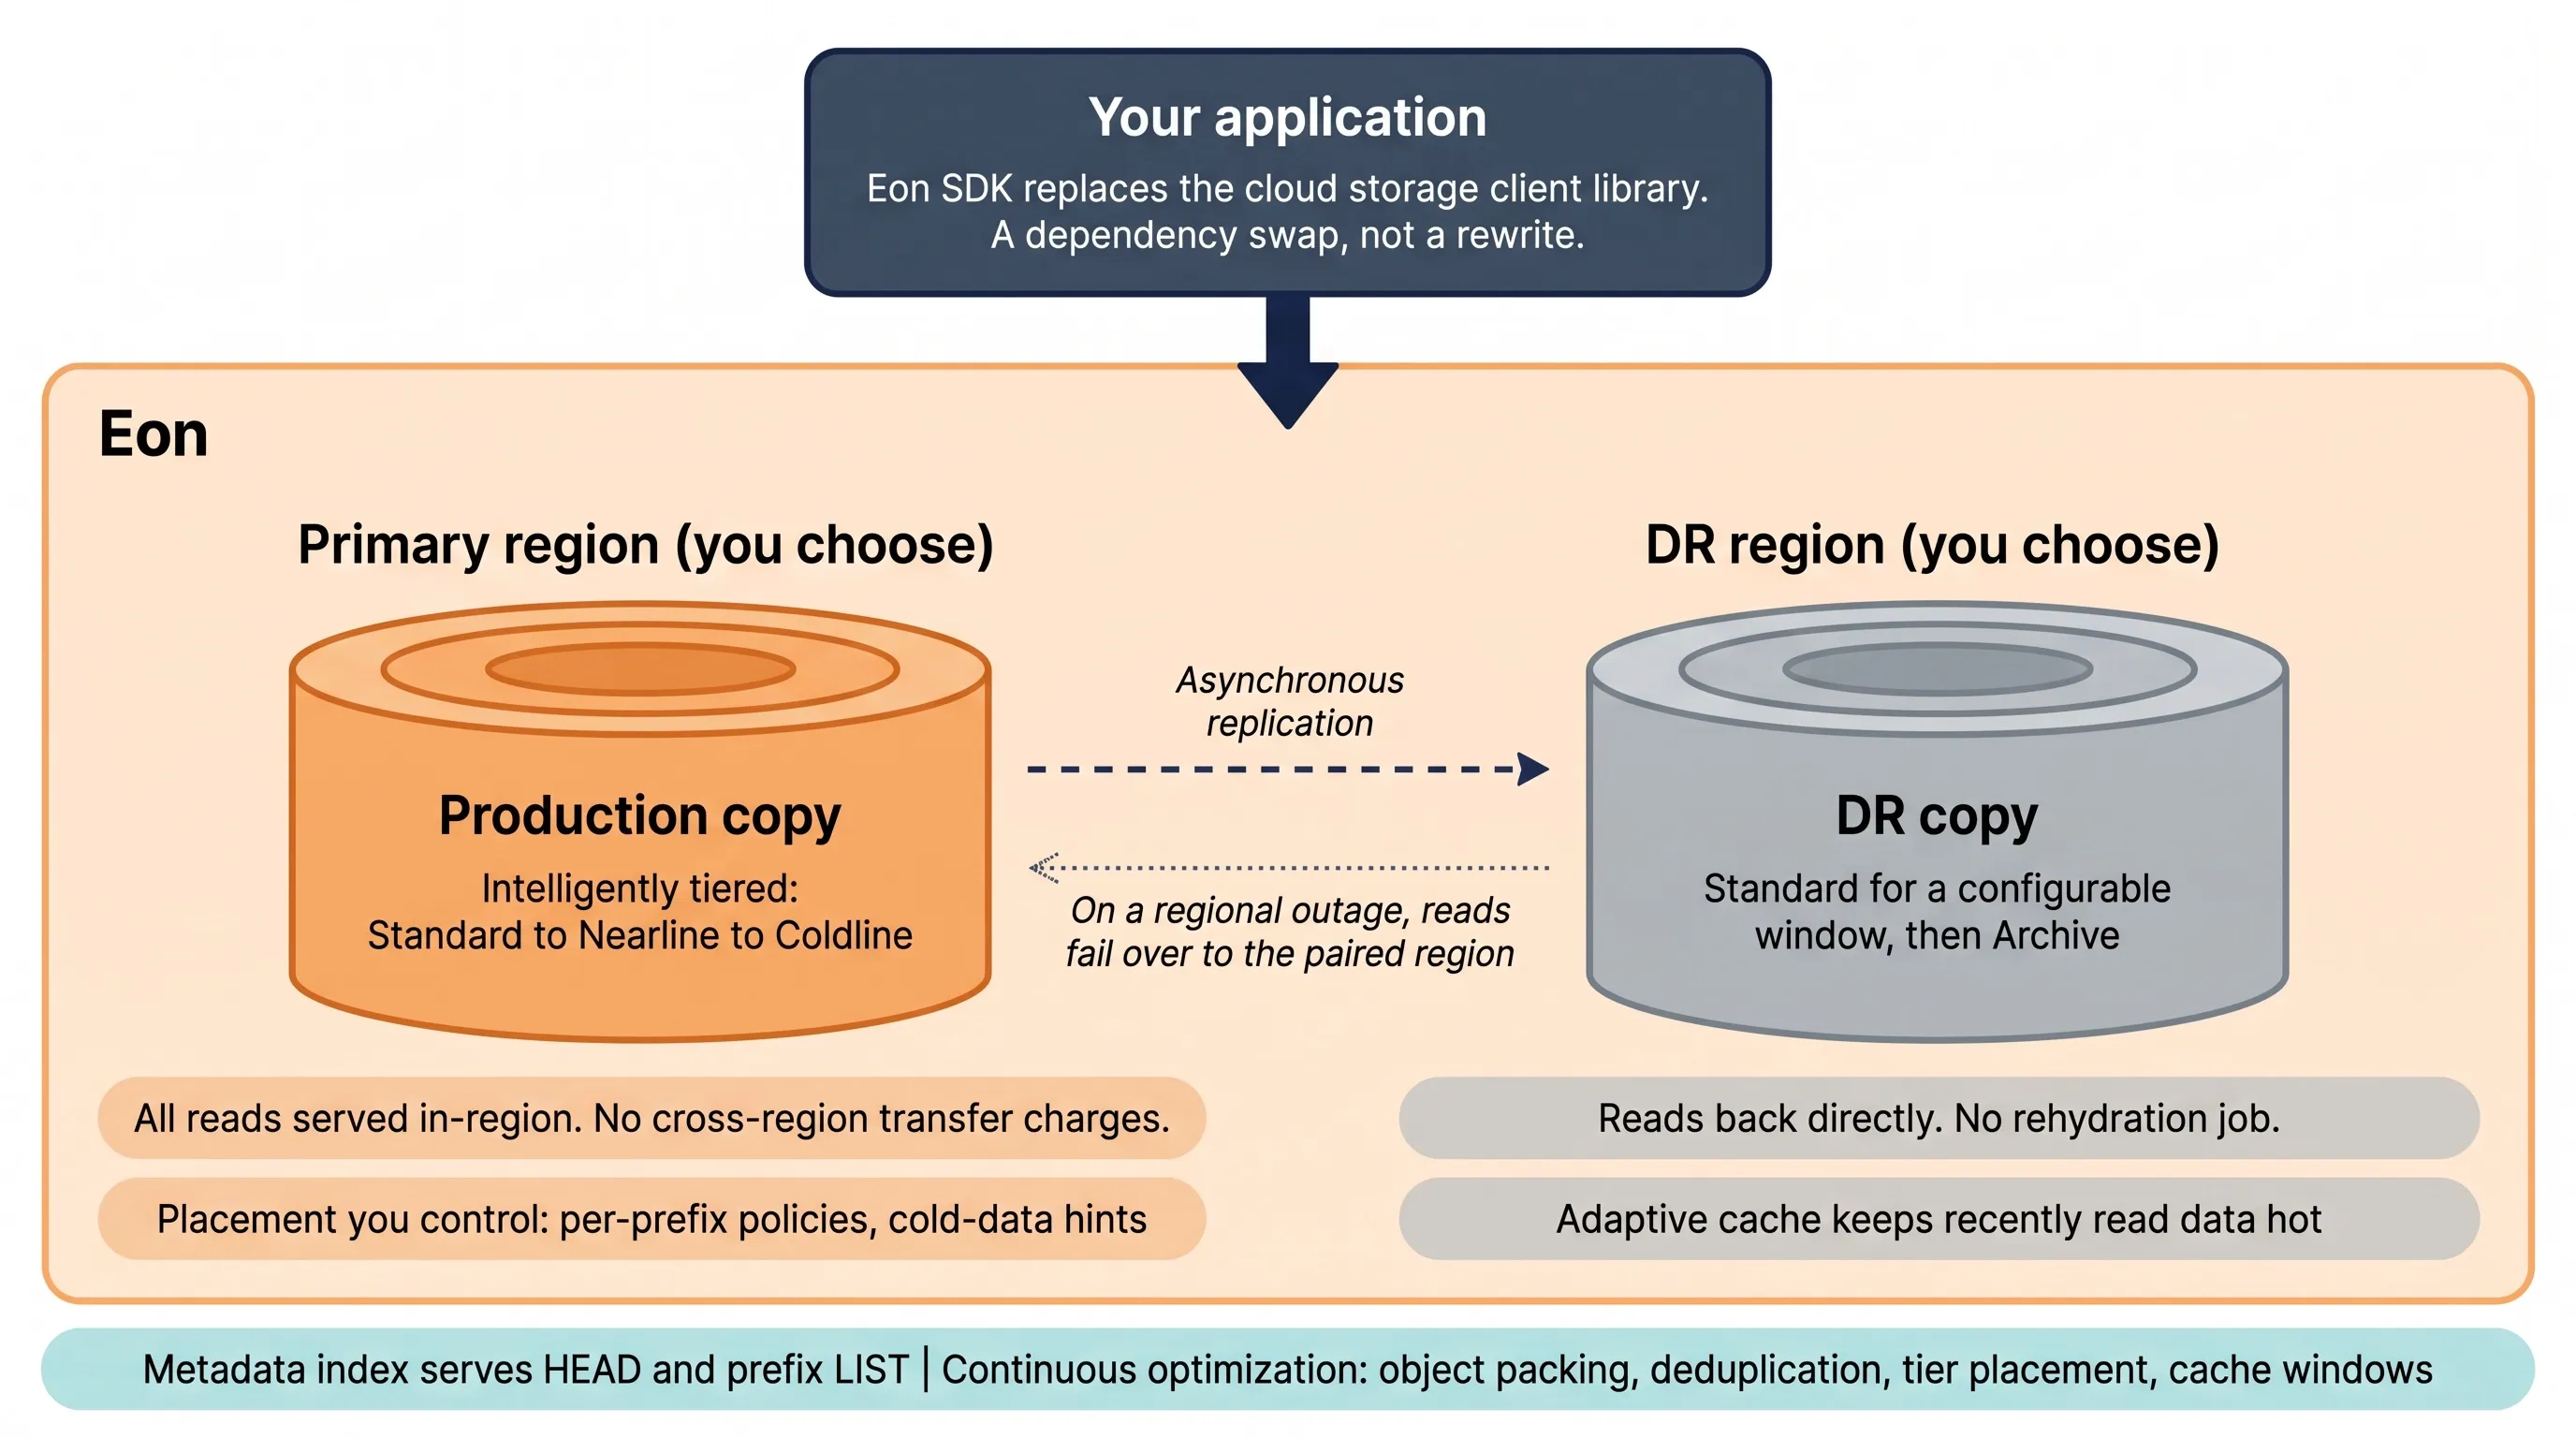
- The DR copy is decoupled and tiered for recovery, not production. It can sit in archive from the start, instead of being locked to the same storage class as the copy you read.
- Small objects are bundled before replication. You pay for one operation per bundle instead of one per object.
- The production copy stays in the region your applications run in. A multi-region bucket bills your everyday reads as cross-region transfer. Eon keeps a copy where the application already is, so those reads never cross a region boundary and there is nothing to charge for.





How Eon handles writes, replication, and tiering
Eon sits between your application and cloud storage as a client library. A write goes into the region your application runs in and is readable there immediately. A second copy is bundled with other objects heading to the same place and replicated to the DR region you picked, where it falls into archive pricing. This is built for petabyte scale and billions of objects, where cost tracks object count as much as data volume. Reads come back from whichever copy is local, and if a region goes down the SDK fails over to the other one.
Write: through a drop-in SDK
Replicate: batched and packed
Tier: each copy at its own price point
AI-era storage without AI-scale costs
A modeled petabyte-scale production estate on Google Cloud, running multi-region buckets with Autoclass, against the same estate on Eon. Both columns are full five-year cost of ownership including Eon's own charges, so they compare directly. The multi-region bill is indexed to 100.
| Five-year cost of ownership | GCS Multi-Region | Eon | Change |
|---|---|---|---|
| Storing the dataBoth copies. On GCS they share one storage class; on Eon each copy is tiered on its own. | 51.3 | 39.9 | 22% less |
| Moving the dataReads billed as cross-region transfer, plus replication on writes | 30.4 | 9.7 | 68% less |
| Operations and feesTiering fees, retrieval, and per-request charges | 18.3 | 16.1 | 12% less |
| Total | 100 | 66 | 34% less |
Indexed figures. Modeled at petabyte scale on Google Cloud list prices before negotiated discounts, with applications reading in their own region.
Storing the data costs less for three reasons. The DR copy is decoupled from the production copy, so it can sit in archive from the start while the copy your application reads stays warm. A geo-redundant bucket applies one storage class to both copies, so the redundant one is priced the same as the copy you actually read. Objects under 128 KiB tier down instead of sitting in Standard indefinitely. And the tiering policy is yours to shape per prefix, rather than one setting for the whole bucket.
Moving the data costs a fraction of what it did, because every read is served from a copy in the same region as the application, rather than billed as cross-location traffic.
A single read of the cold copy can cost you a year of Standard-rate storage on Autoclass. A read promotes the object back to Standard, and it takes a year of inactivity to move back down to archive, so pulling a large slice of cold data during an incident re-warms it at Standard rates for the next twelve months. Eon reads the object from archive and serves it from a cache that is discarded once the incident is over. The DR copy remains in a lower-cost storage tier and is accessed primarily during recovery.
Explore more from Eon
FAQs


Bring us your bill
Send your object-storage footprint, access patterns and region layout, and we'll model your costs line by line against what you pay today.