Eon yukon
Always-fresh data for agents and analytics. A fraction of the infrastructure.





From raw events to agent-ready data in under a minute
Eon Yukon combines high-performance ingestion and continuous table maintenance to keep data fresh, organized, and ready for agents, analytics, and AI with less compute and engineering overhead.
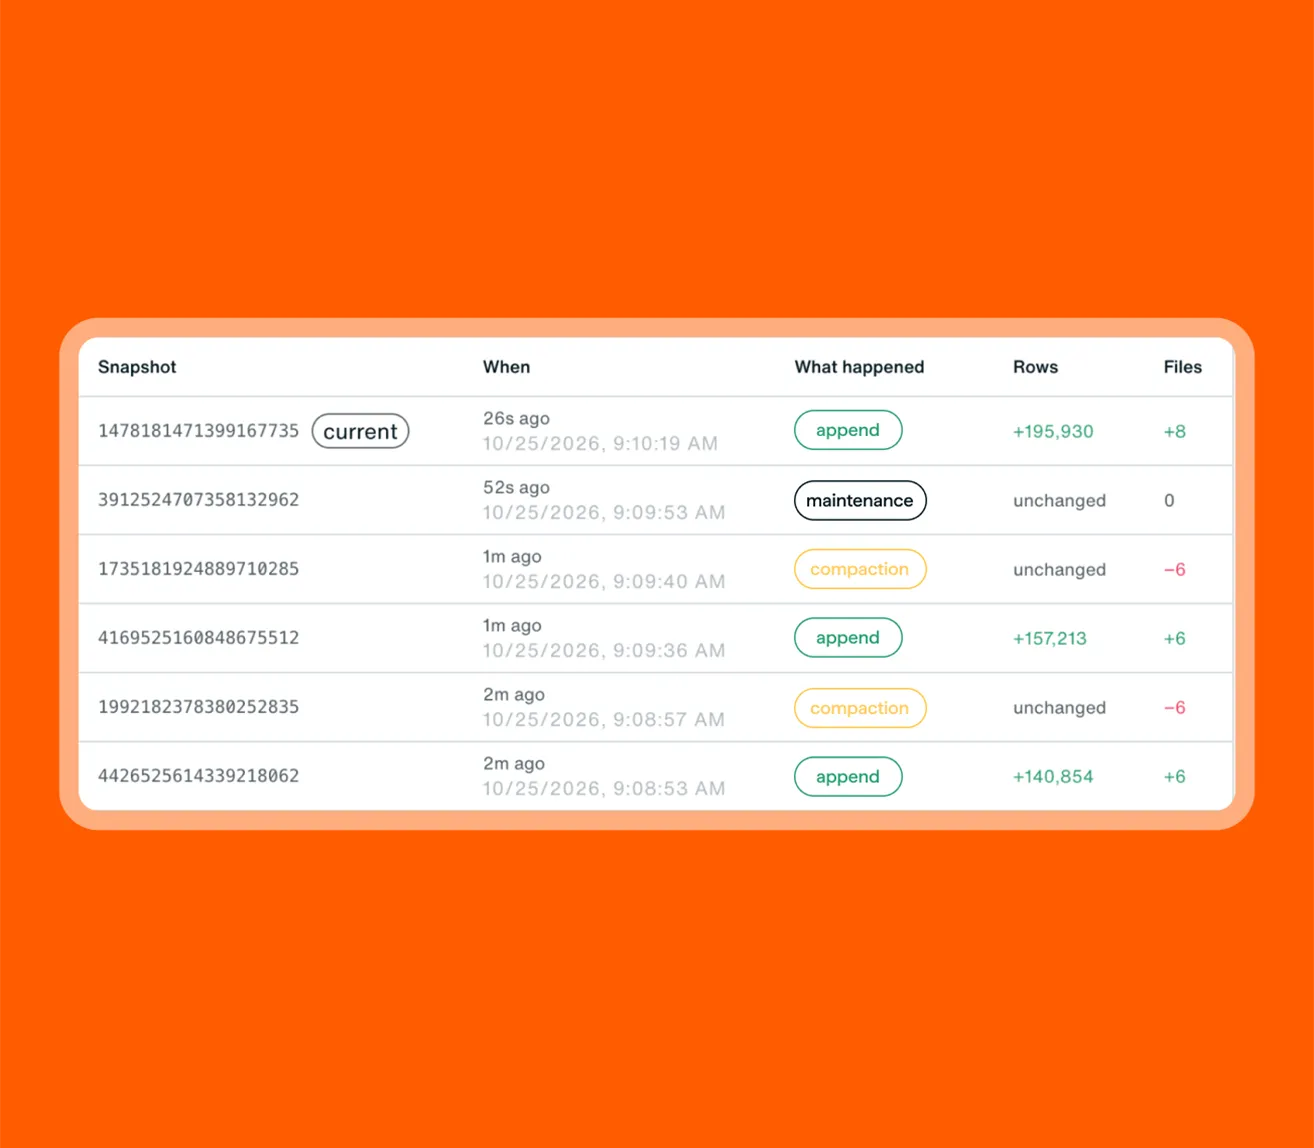
Clean, continuously maintained tables
Turn incoming events into Apache Iceberg tables with built-in deduplication and compaction, queryable in under a minute.
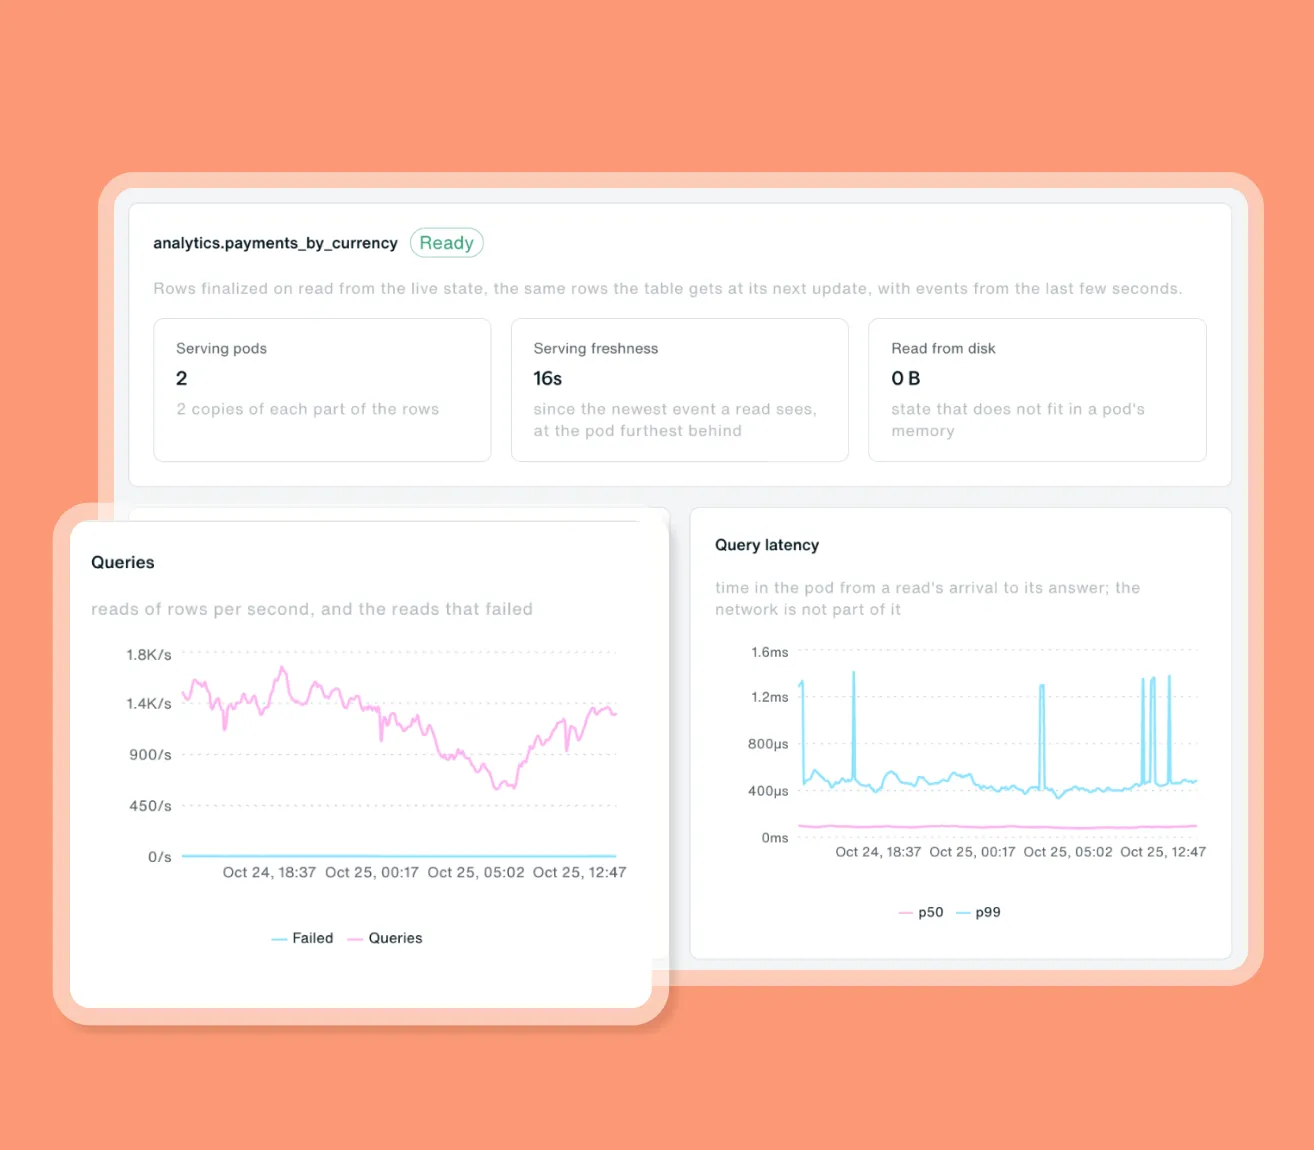
Aggregations that stay current
Maintain configured real-time aggregations as data arrives, reducing downstream processing without separate batch jobs to schedule or tune.
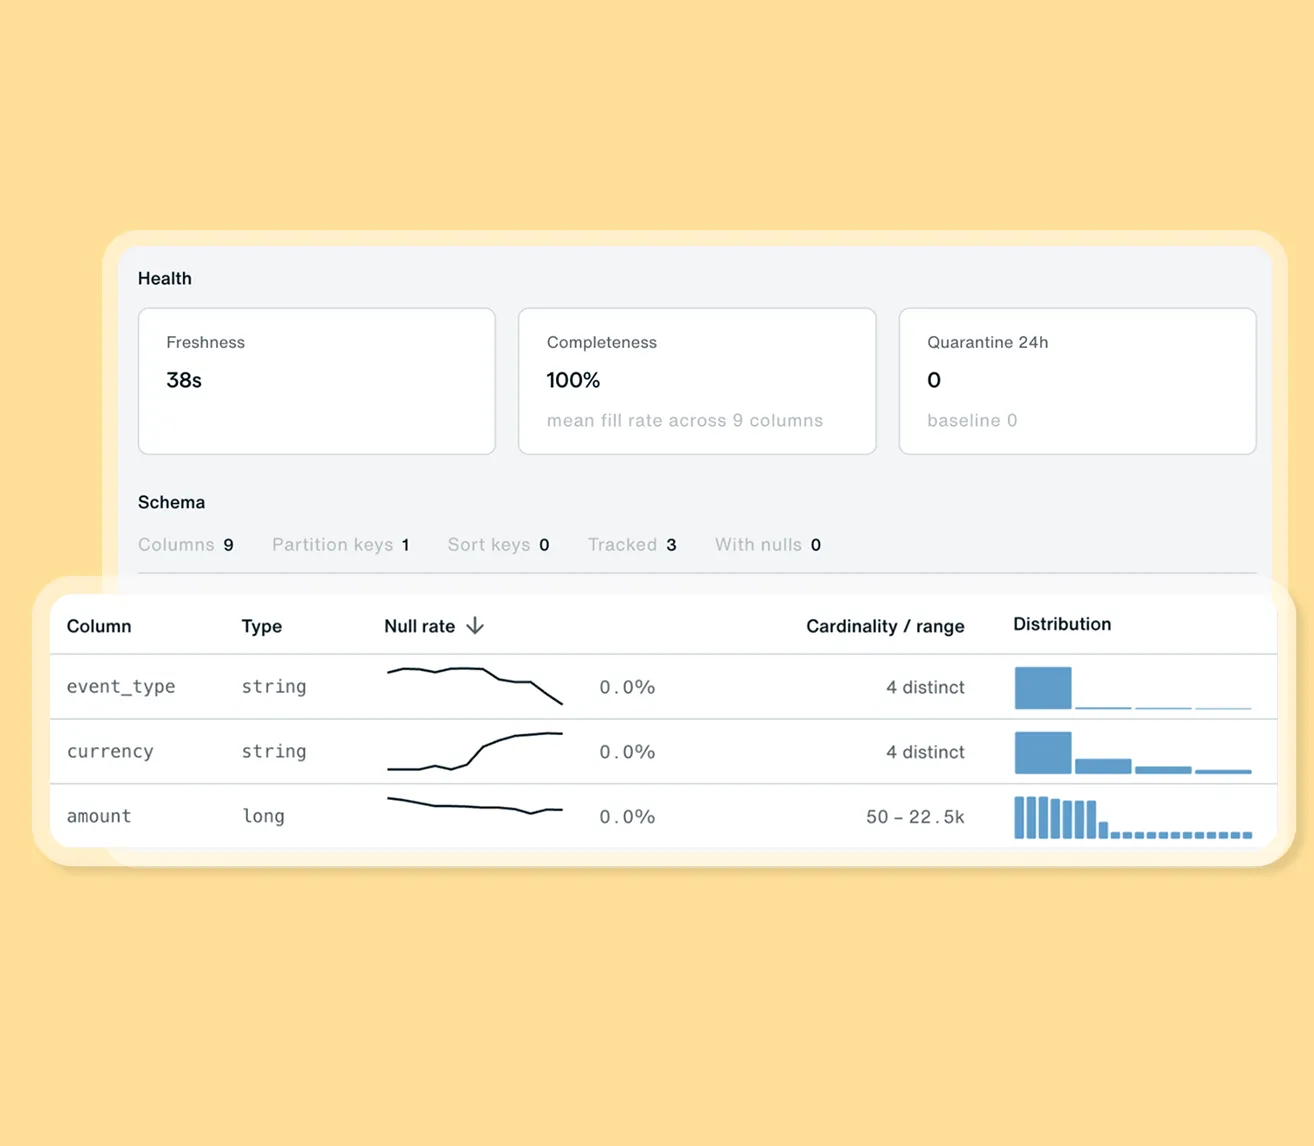
Context that powers smarter queries
Capture column-level statistics, samples, and changes during ingestion to help agents understand the data and accelerate supported queries.
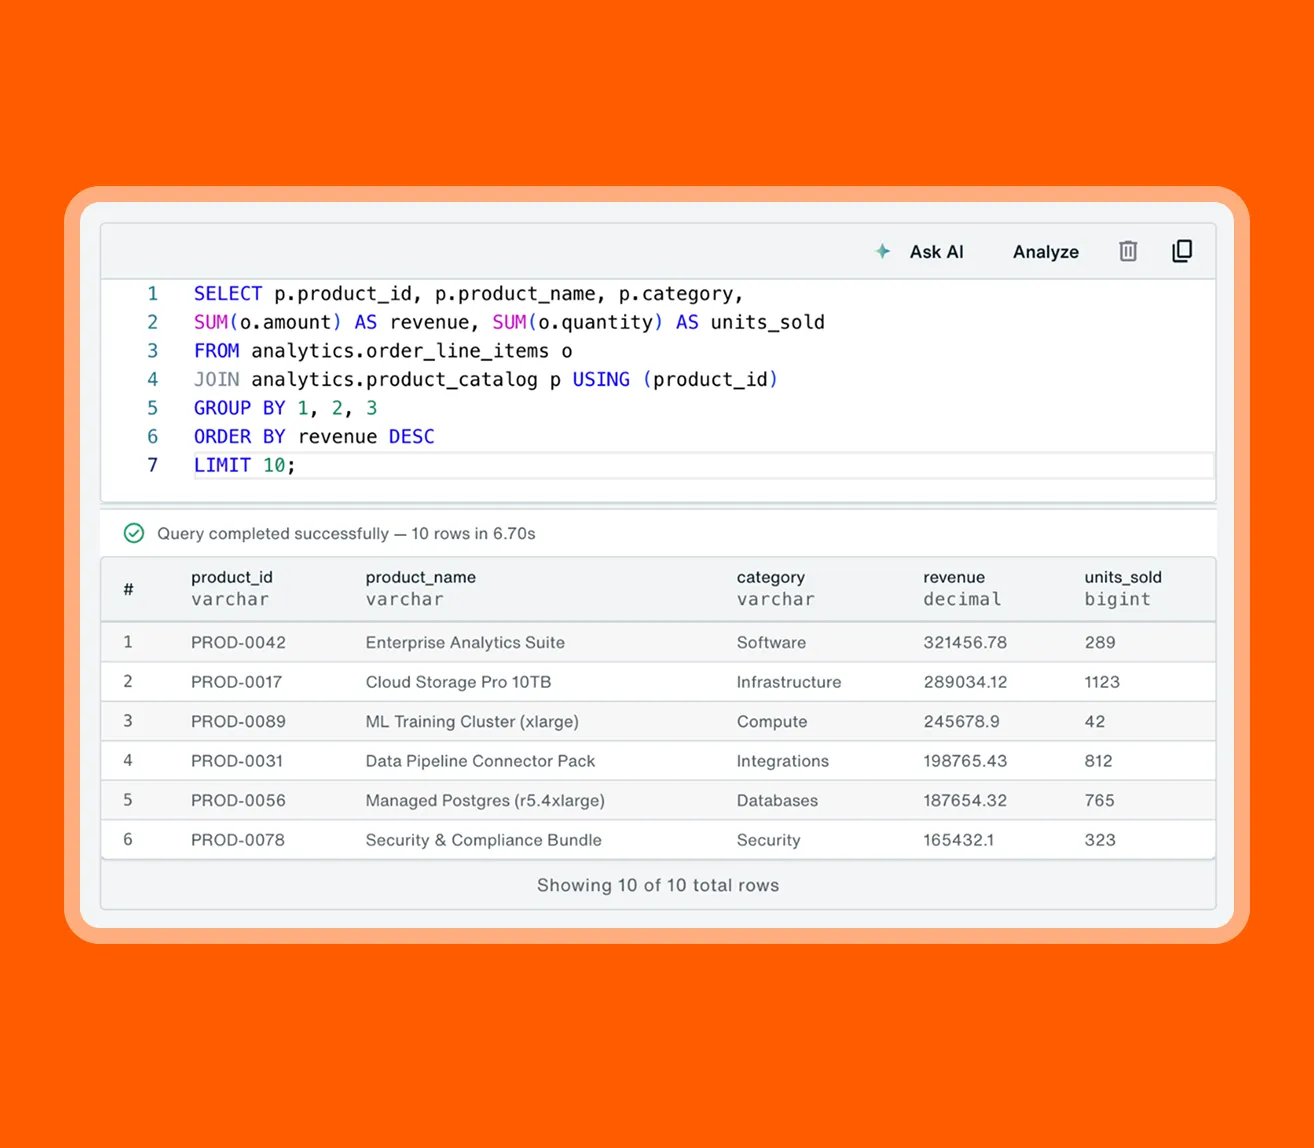
Open tables you own
Eon Yukon stores Apache Iceberg tables in object storage in your AWS or Google Cloud account. Query them with Eon's serverless SQL or the Iceberg-compatible engines and catalogs you already use, alongside data protected by Eon Data Protection.
Prepares data. Builds context. Keeps both current.
One fully managed engine for ingestion, preparation, context, and query.
Inside Eon Yukon
Take a deeper look into the technology that powers Eon’s platform
Prepares data as it arrives
Combine streaming ingestion, data preparation, aggregations, and table maintenance in one managed engine, keeping tables ready without separate pipeline jobs.
Builds context as data changes
Capture column-level statistics and track changes during ingestion. Make that information available to agents and query engines to guide exploration and accelerate supported queries.
Query without managing compute
Use serverless SQL with metadata-driven acceleration and query planning in milliseconds. Pay per query, with zero idle compute costs.
Serve live state directly to applications
Access the latest state of configured aggregates by key in under a millisecond through a Redis-compatible API. Serve applications and agents without separate caches or synchronization pipelines
Watch Yukon keep up with GitHub, live
Public GitHub activity streams into an open Iceberg table through Eon Yukon and is queried as it lands. The numbers below are live.
Learn more from our experts
Frequently Asked Questions
Eon Yukon brings high-performance ingestion, data preparation, real-time aggregations, continuous table maintenance, and serverless SQL together in one fully managed engine. It writes data directly to your cloud object storage in the open Apache Iceberg format, keeps the tables up to date, and captures context as data arrives. This gives your analytics teams, applications, and AI agents fresh, query-ready data with less compute and engineering overhead.
Eon handles ingestion and table maintenance together, with built-in deduplication, compaction, and configured real-time aggregations. This reduces separate processing jobs and repeated downstream work. Metadata captured during ingestion also accelerates supported queries. Rise runs Eon Yukon in production at 200 billion events per day. Read the Rise case study
As Eon prepares data, it captures column-level statistics, samples, and information about what changed. Agents can use this context to understand tables, investigate changes, and determine what to query next, reducing repeated discovery and preparation.
Yes. Eon Yukon is a standalone product that ingests and prepares live data independently of Eon Data Protection. Teams using both can also make protected data available alongside live data for analytics, applications, and AI.
Eon Yukon prepares incoming live data, while Eon’s Zero-ETL capabilities make data protected by Eon Data Protection available as open Apache Iceberg tables. Agents and analysts can query current activity and historical records without building separate extraction pipelines.
No. Eon works with supported Iceberg-compatible engines and catalogs, so you can keep your existing tools while consolidating ingestion, preparation, and table maintenance. You can also use Eon’s serverless SQL without managing query infrastructure.
No. Eon Yukon also supports high-volume streaming analytics, dashboards, reporting, and production applications. Alongside SQL access to prepared tables, a Redis-compatible API provides sub-millisecond access to live state for latency-sensitive applications.
Eon Yukon writes tables to object storage in your own AWS or Google Cloud account, in the open Apache Iceberg format rather than a proprietary one. Your existing Iceberg-compatible engines and catalogs can query them, and if you stop using Yukon, the tables stay in your account and remain readable.
Enterprise-grade, single-tenant architecture