Serverless Queries
Query fresh Iceberg tables with Eon Yukon. No cluster to run.
Eon Yukon answers SQL and Spark Connect queries on the Apache Iceberg tables it prepares, planning in milliseconds from the statistics written at ingest. Data teams, applications and AI agents get fast answers, billed per query, with nothing running when idle.
Most of the answer is ready before you ask
Agents ask thousands of questions. Eon Yukon plans each one in milliseconds from statistics written at ingest, and you pay only while it runs.
Plans from metadata, not manifests
Eon Yukon plans queries in milliseconds from the column statistics, key indexes and search indexes it writes at ingest, and reads only the columns a query needs.
Pay per query, nothing running when idle
There is no cluster to size for the peak or keep warm overnight. Each query runs serverless next to the data, and nothing runs when nobody asks.
Spark jobs, unchanged
Run PySpark and SQL jobs serverless through Spark Connect, with no cluster to size or keep running between queries. RDD and custom-JVM jobs and GPU training stay on Spark.
Built for agent questions
Key lookups, full-text search, and counts and percentiles without a scan let an agent understand a table and decide what to query in one call instead of a string of exploratory queries.
From the lake to the answer
Eon Yukon writes open-format tables to object storage in a dedicated account in your region, shared with you, or in your own account with BYOC, queries them directly, and leaves them open to the engines and catalogs you already use.
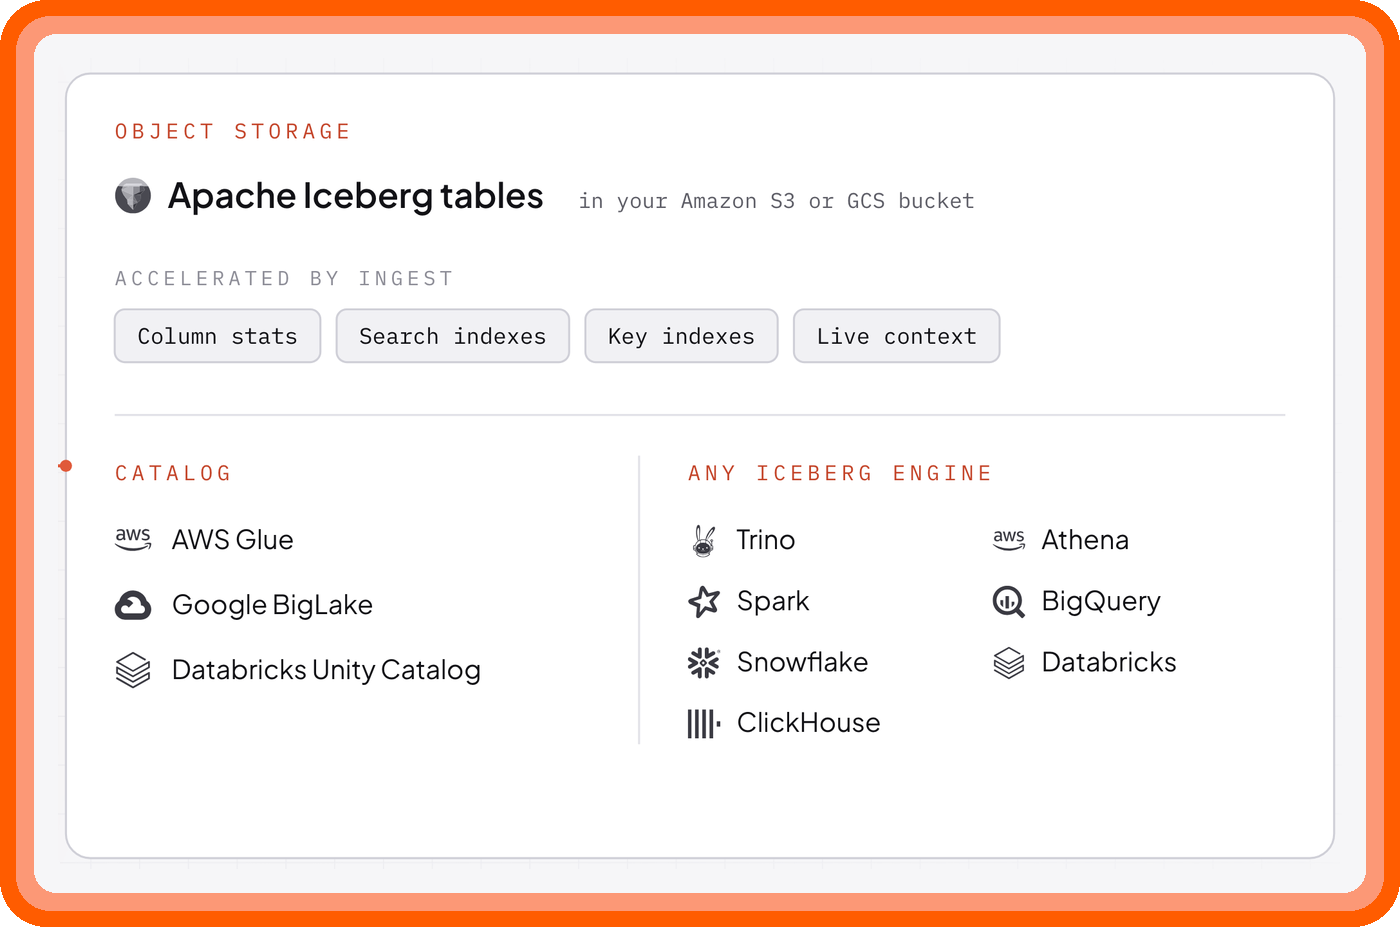
Eon Yukon writes Apache Iceberg tables to Amazon S3 or GCS and registers them in AWS Glue, Google BigLake or any Iceberg REST catalog. Column statistics, key and search indexes and table context are written in the same commit.
SQL, Spark Connect and MCP requests reach Eon Yukon, which plans from those statistics instead of reading manifests and opens only the files and columns it needs.
Each query runs on zero-disk distributed compute next to the data, and rows stay in the data plane. Snowflake, Databricks, Trino, Athena and any other Iceberg engine keep reading the same tables.
Put fast, serverless SQL to work
01
Answer analyst agent questions
An analyst agent reads what every table means over MCP, then answers in under a second.
02
Run Spark batch ETL serverless
Spark jobs on clusters sized for the nightly peak run unchanged over Spark Connect, serverless, against the same Iceberg tables. RDD and custom-JVM jobs and GPU training stay on Spark.
03
Retire always-on query clusters
Spark, Trino or Presto clusters kept up for ad-hoc queries give way to per-query compute, with nothing running when idle.
04
Explore fresh streaming data
Dashboards and investigations query tables that are seconds behind the source, with upserts and deduplication already applied.
See how Eon works in your environment
Bring a query you run on a cluster today and we will show you the same query on Eon Yukon, with speed and cost per query side by side.