Cut the cost of keeping data fresh
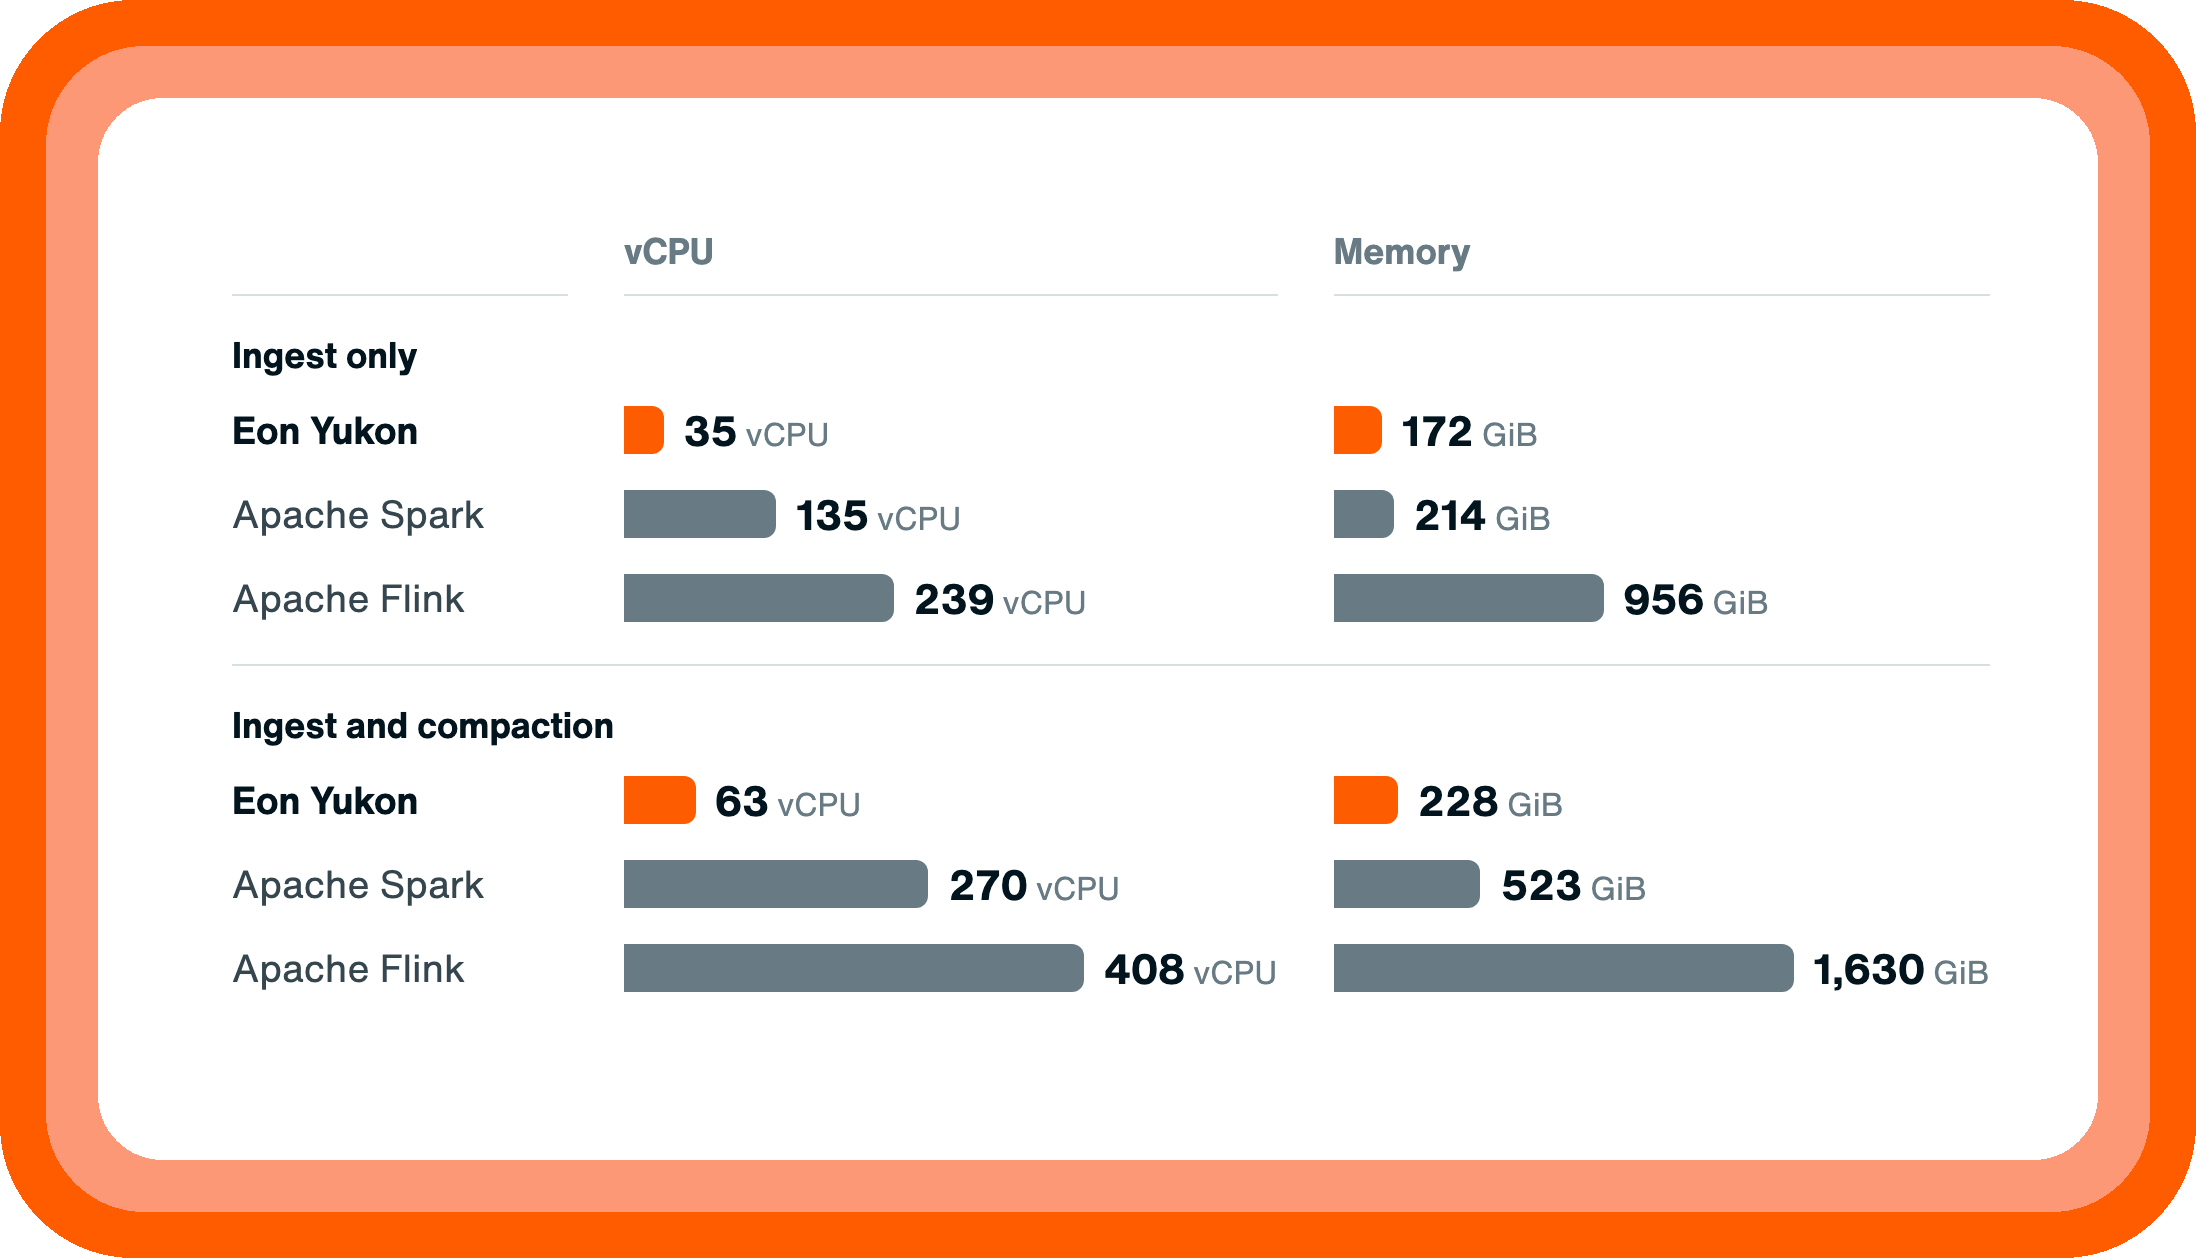
Eon Yukon ingests and maintains tables on 4× to 7× less compute than Spark and Flink, with maintenance included and no idle query costs.
Data processing costs grow faster than data
General-purpose streaming engines need large clusters to keep up with high-volume streams, then more compute to compact the small files they leave behind. Teams size query clusters for the busiest hour and pay for them while they wait. Every new stream and every idle hour adds to the bill.
Too much compute to keep up
High-volume streams demand large clusters. Uneven traffic pushes teams to add even more capacity for the busiest part of the pipeline.
Maintenance billed on the side
Keeping tables fast takes additional jobs and compute, adding costs beyond ingestion.
Clusters paid for all day
Teams size query and ETL clusters for the busiest hour and keep them warm between jobs, paying for capacity that often sits idle.
How Eon lowers processing costs
Eon Yukon reduces compute costs across ingestion, processing and queries. It lands data efficiently, keeps tables optimized with built-in compaction, and prepares the tables you need in one pass. Queries and Spark jobs use compute only while they run. Your data stays in open Iceberg tables. Choose a dedicated account in your region, shared with you, or deploy in your own account.
Less compute to ingest and maintain tables
Eon uses less compute to land event-level data and keep tables compacted and ready to query. Continuous compaction, sorting and cleanup are built in, with no separate maintenance jobs to run or pay for.
Our public benchmarks show Eon Yukon uses 4× to 7× less compute than Spark and Flink for ingestion and compaction combined.
Get more from a single pass
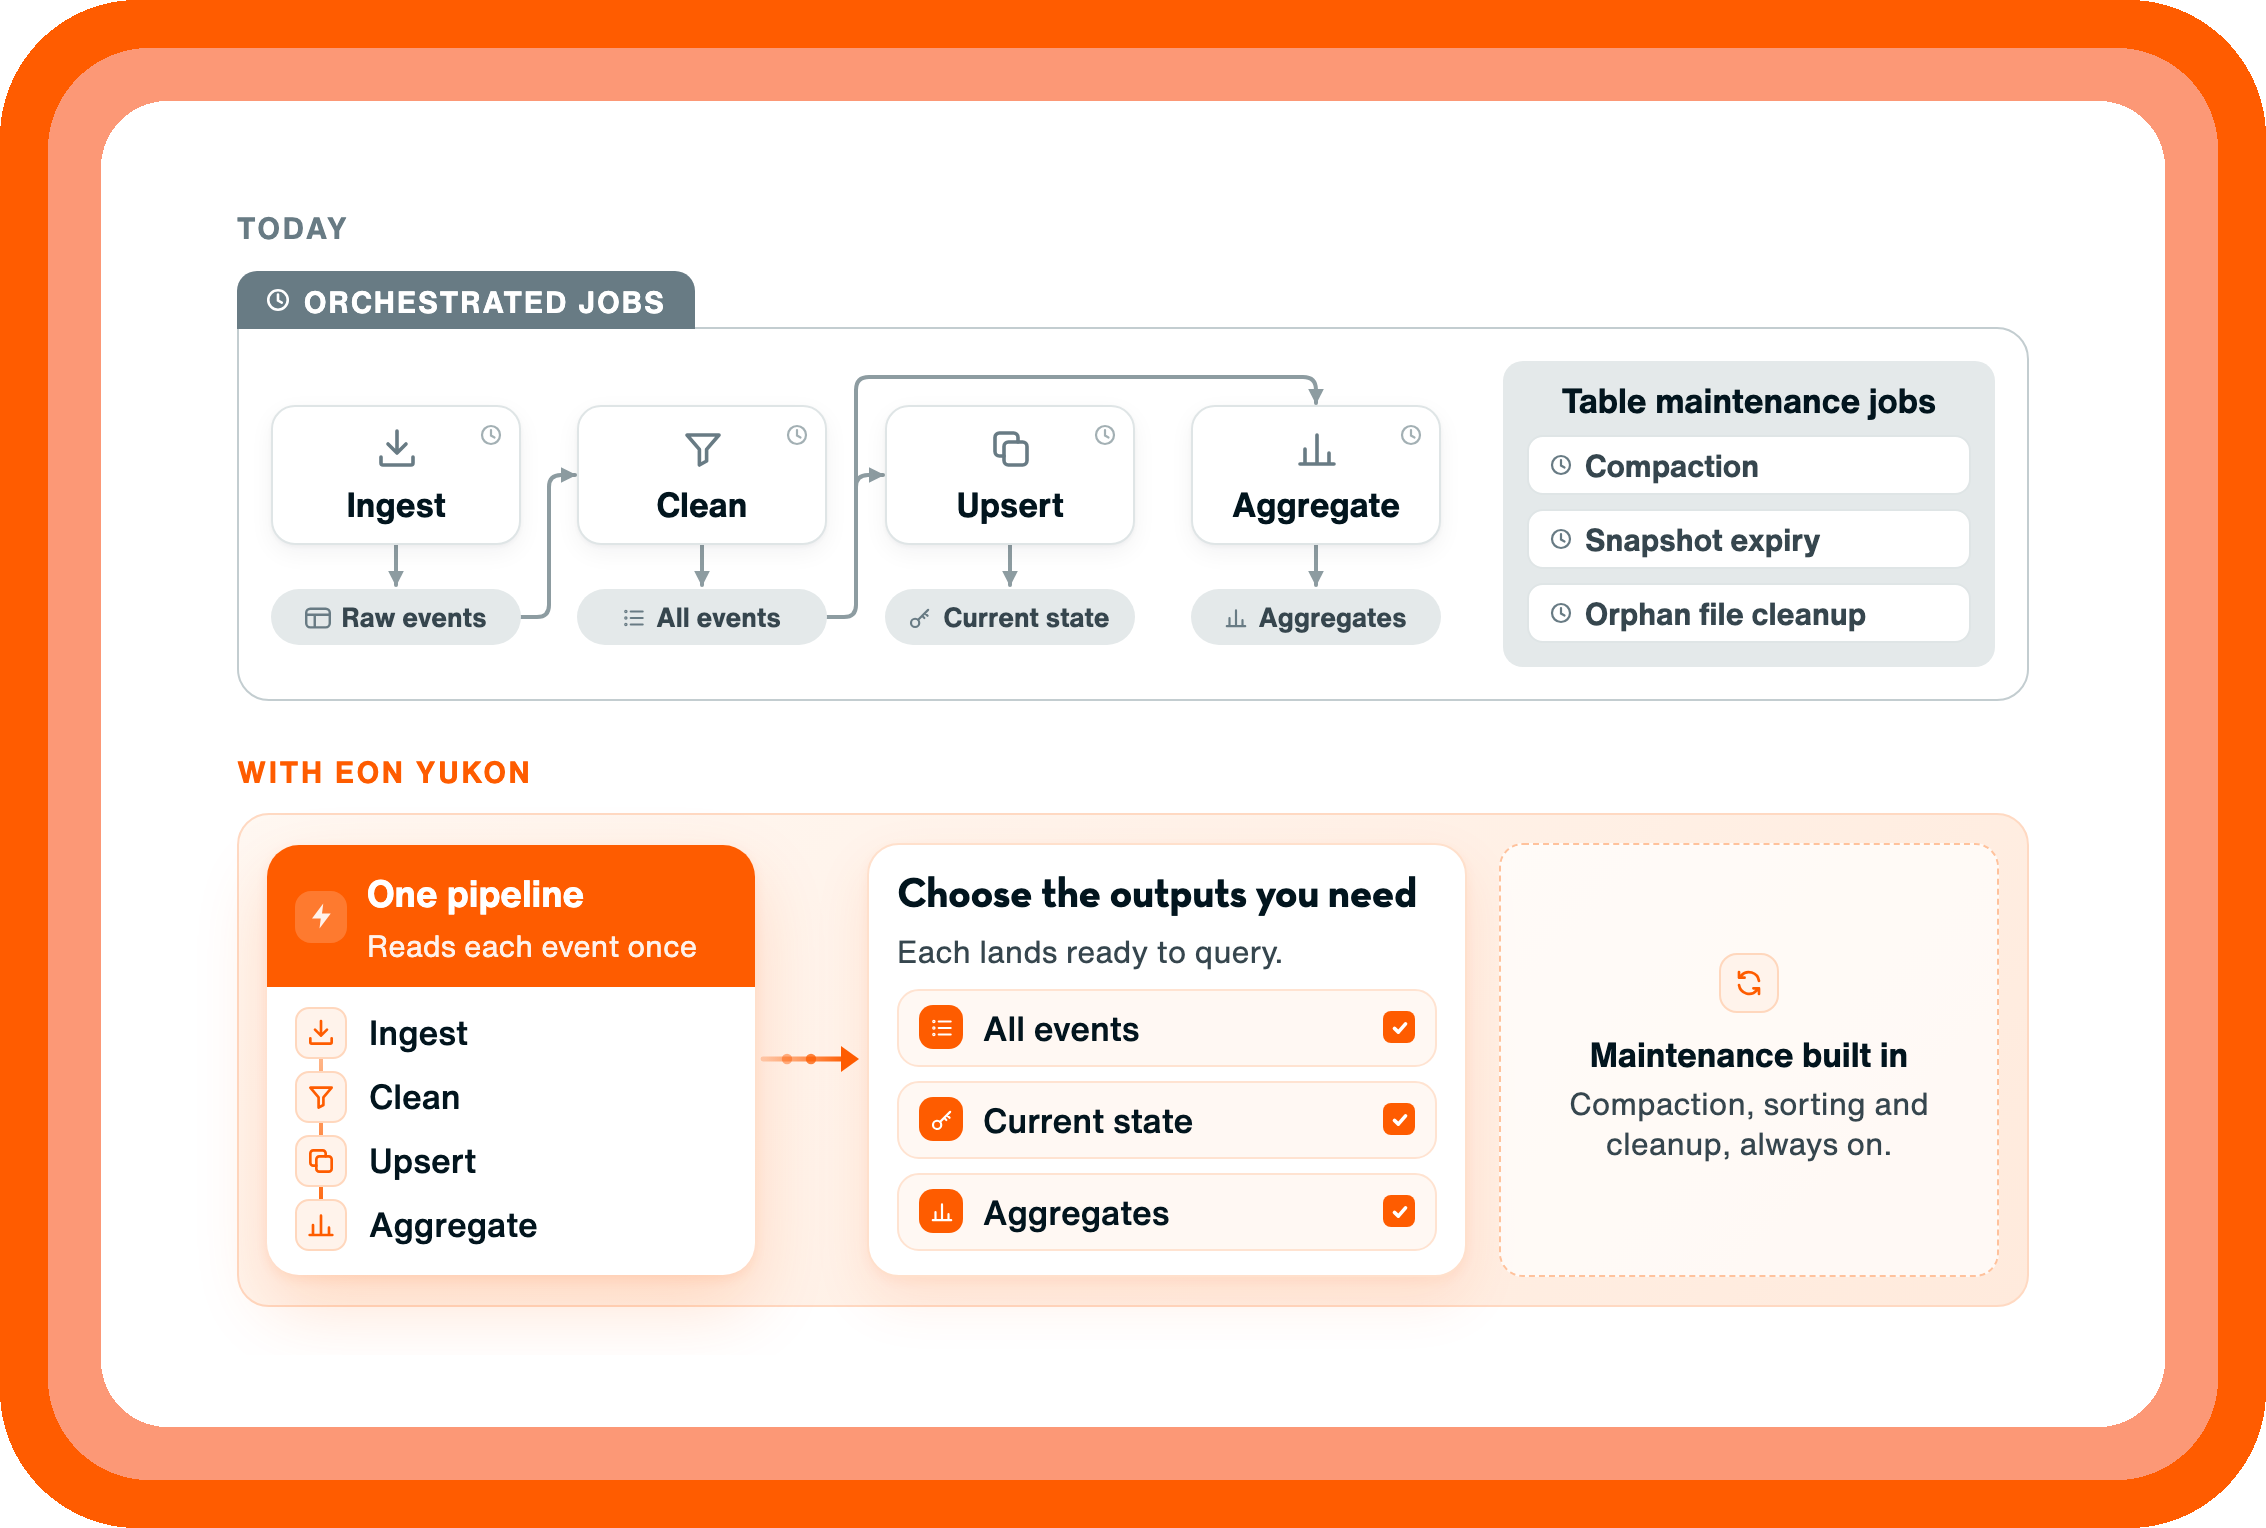
Prepare current records and live summaries alongside event-level data, without paying for separate jobs to reread and process it.
No idle query compute
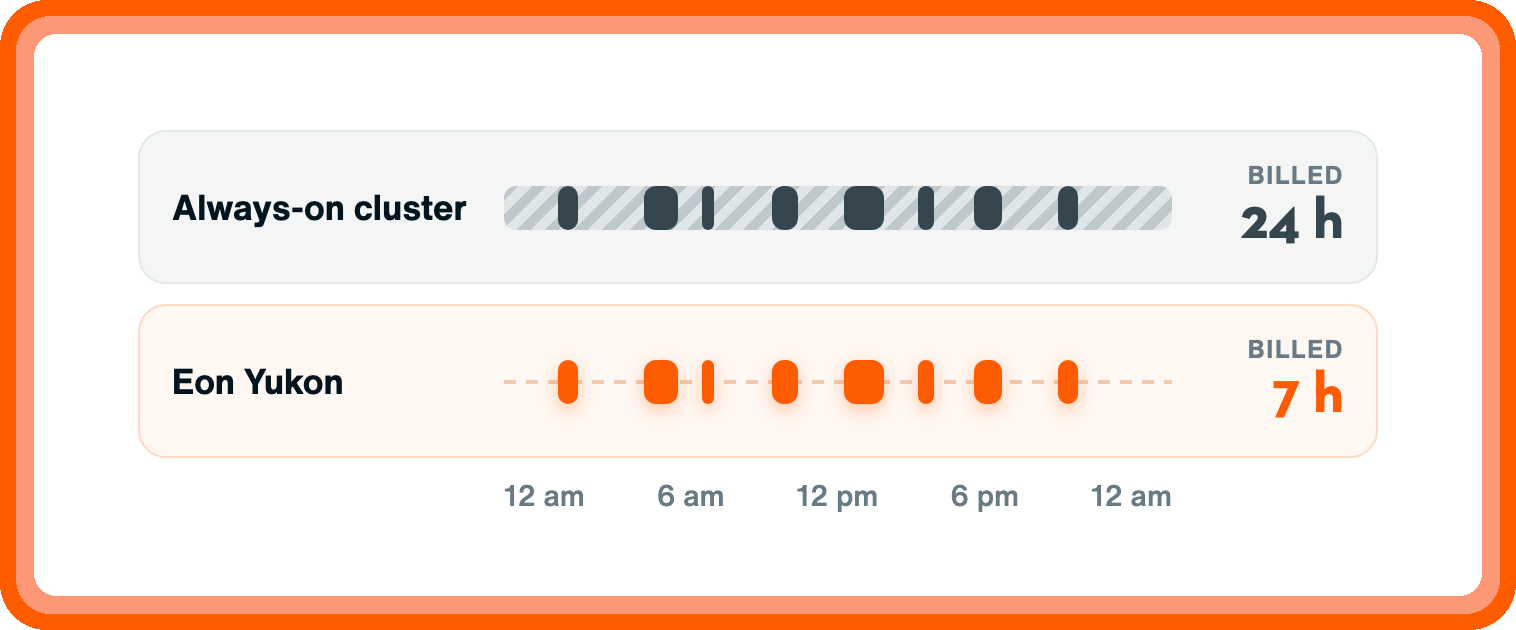
Pay for queries only while they run, with no cluster to keep warm between questions. Existing Spark batch jobs run unchanged over Spark Connect with no cluster to size.
See how Eon works in your environment
Bring a pipeline you pay for today and we will show you the same data landing in Eon Yukon tables, with compute and cost compared side by side.