One pipeline from the stream to a query-optimized table
Eon Yukon combines ingestion, SQL transformations, deduplication and continuous table maintenance in one managed pipeline. Define the tables you need, and Eon Yukon handles the work to keep them fresh and ready to query.
A simple table takes a stack of jobs
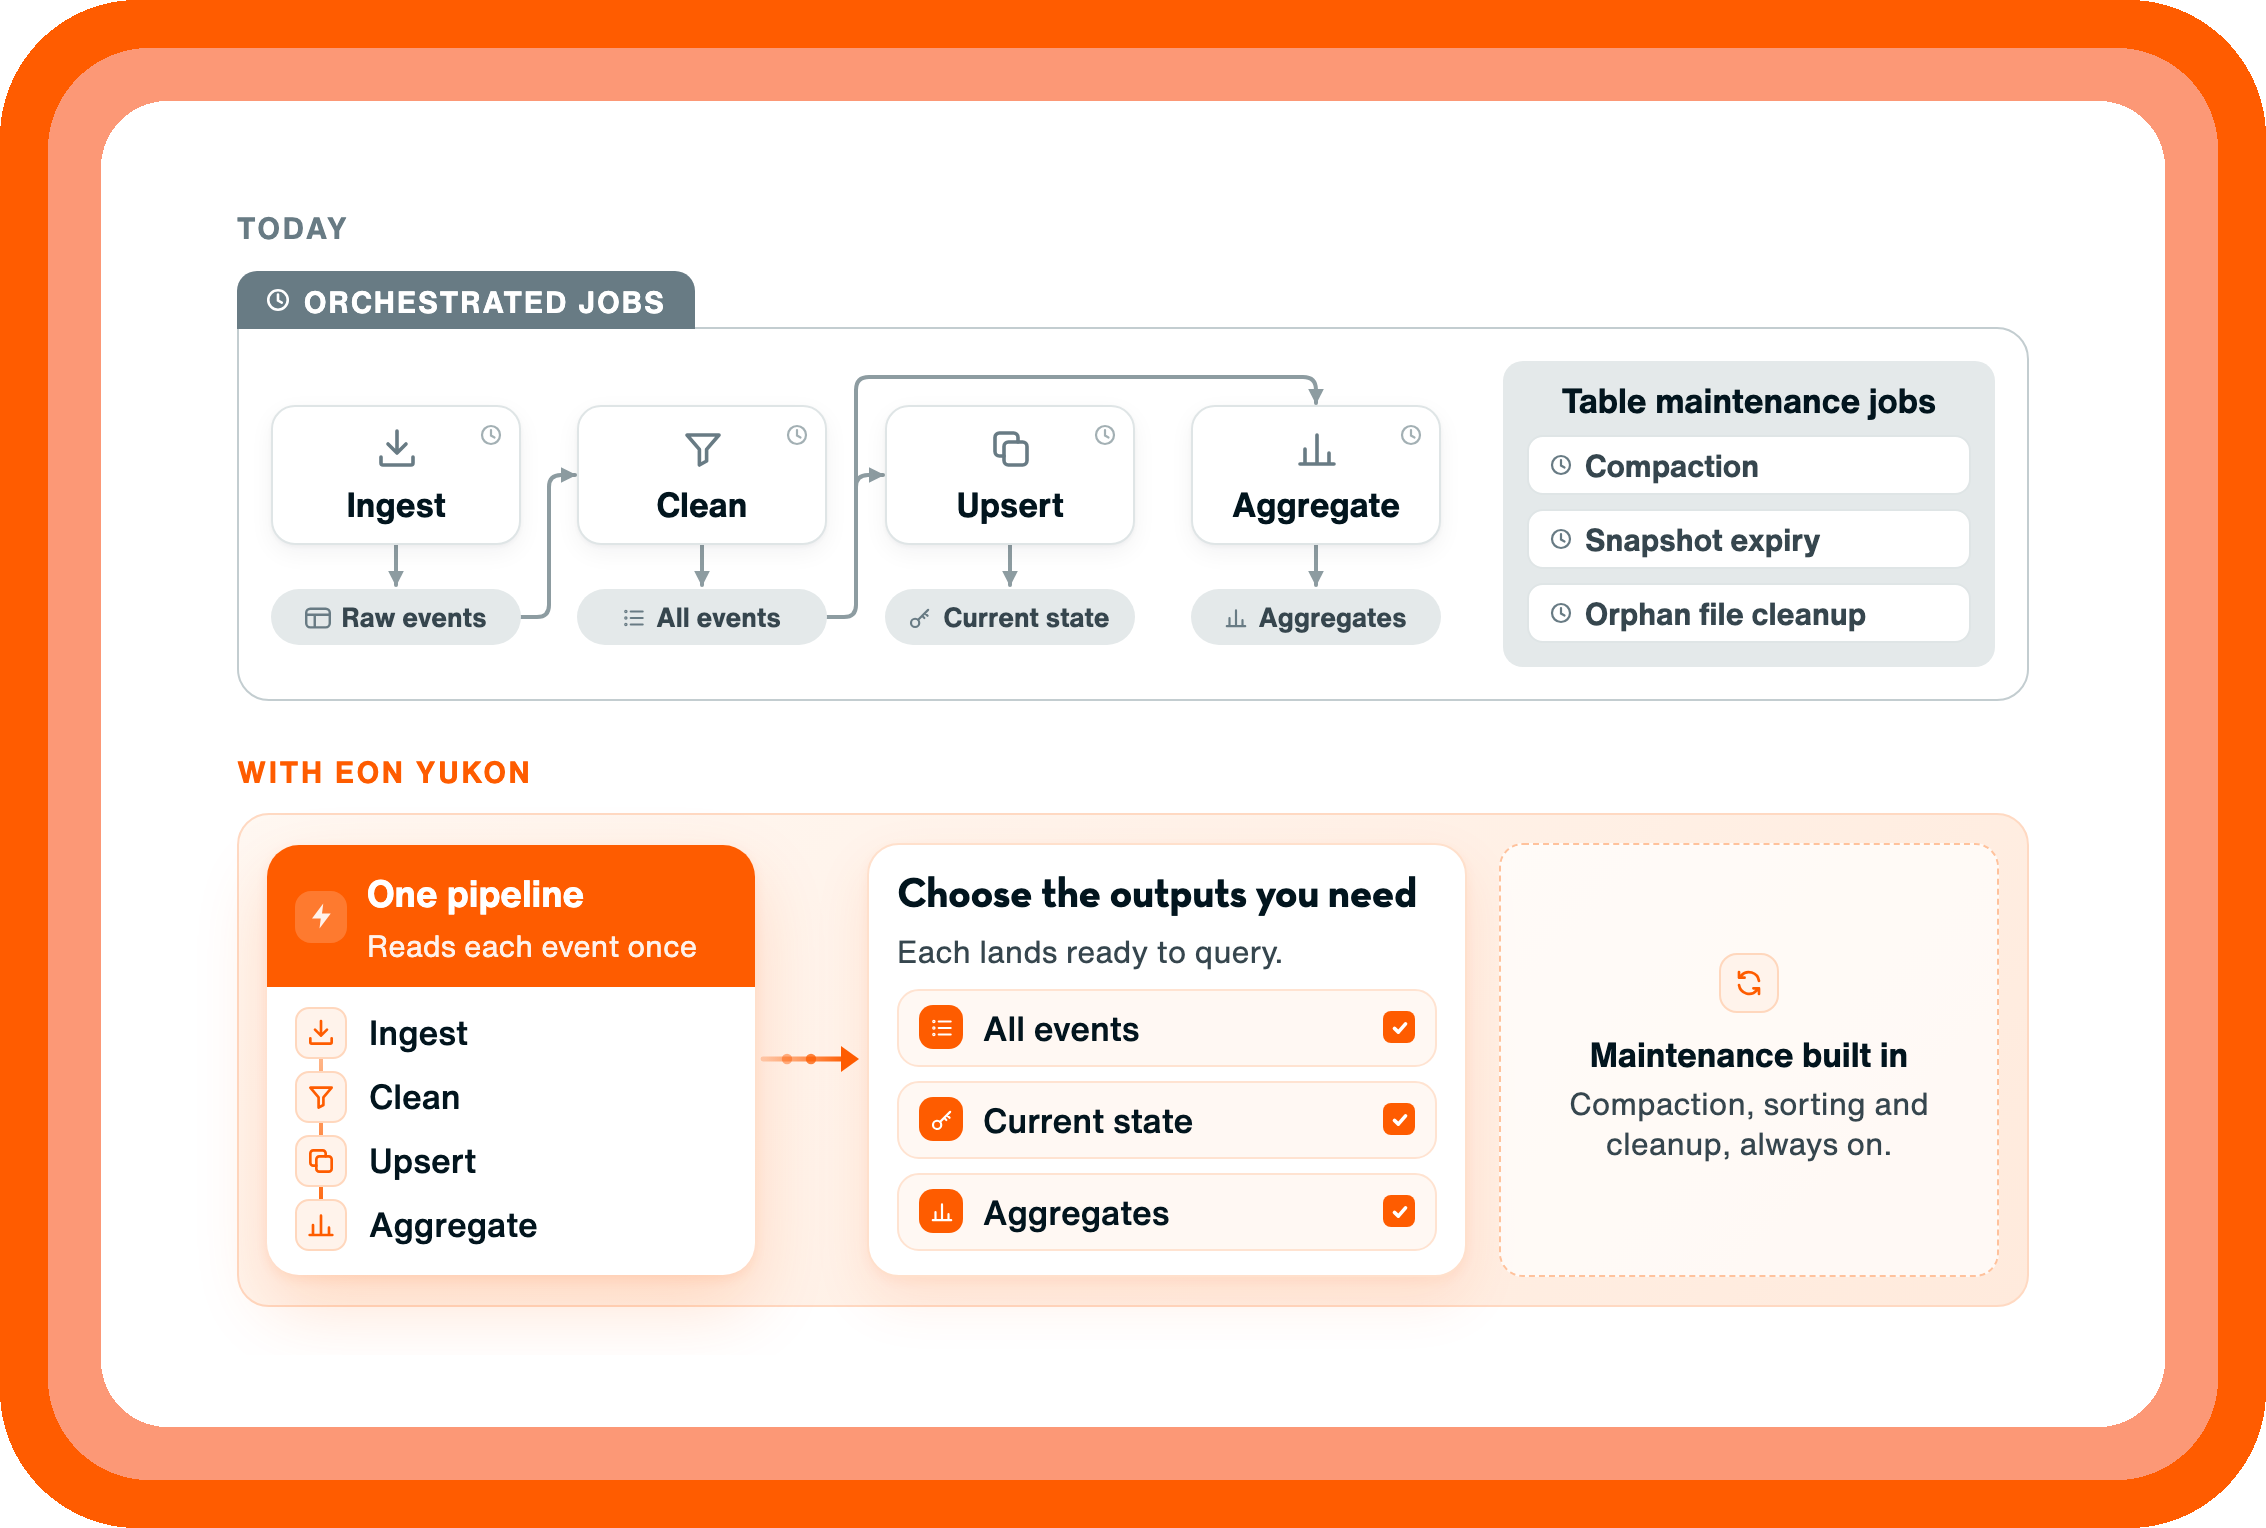
Keeping streaming tables fresh and fast takes more than an ingestion job. Compaction, sorting and cleanup need ongoing attention, while transformations and aggregations add more jobs to operate. Each brings configuration, monitoring and troubleshooting, making the pipeline harder to manage as requirements grow.
Too many moving parts
Every new processing job adds dependencies, configuration and another place for failures. Your team ends up maintaining the pipeline instead of building the data products it supports.
More passes, more cost and delay
After ingestion, separate jobs reread the same data to clean it, apply updates and build summaries. Each pass adds cost and another wait before the data is ready.
Schema changes break pipelines
New fields and changing data formats can mean code updates, restarts and more maintenance for your team.
On-call for the plumbing
Engineers spend their time on retries, backfills, checkpoints and small-file cleanup instead of the data products the business asked for.
How Eon simplifies the pipeline
Describe the table you need. Eon Yukon handles ingestion and ongoing table maintenance in one managed pipeline. Your team gets fresh, query-ready data in open tables, with fewer jobs to build and fewer moving parts to maintain. Configure pipelines directly or through your AI agents.
The outputs you need, without the extra jobs
Keep every event, maintain current records or build live summaries. Eon Yukon produces the tables you choose in one pass, with maintenance built in.
No tuning required
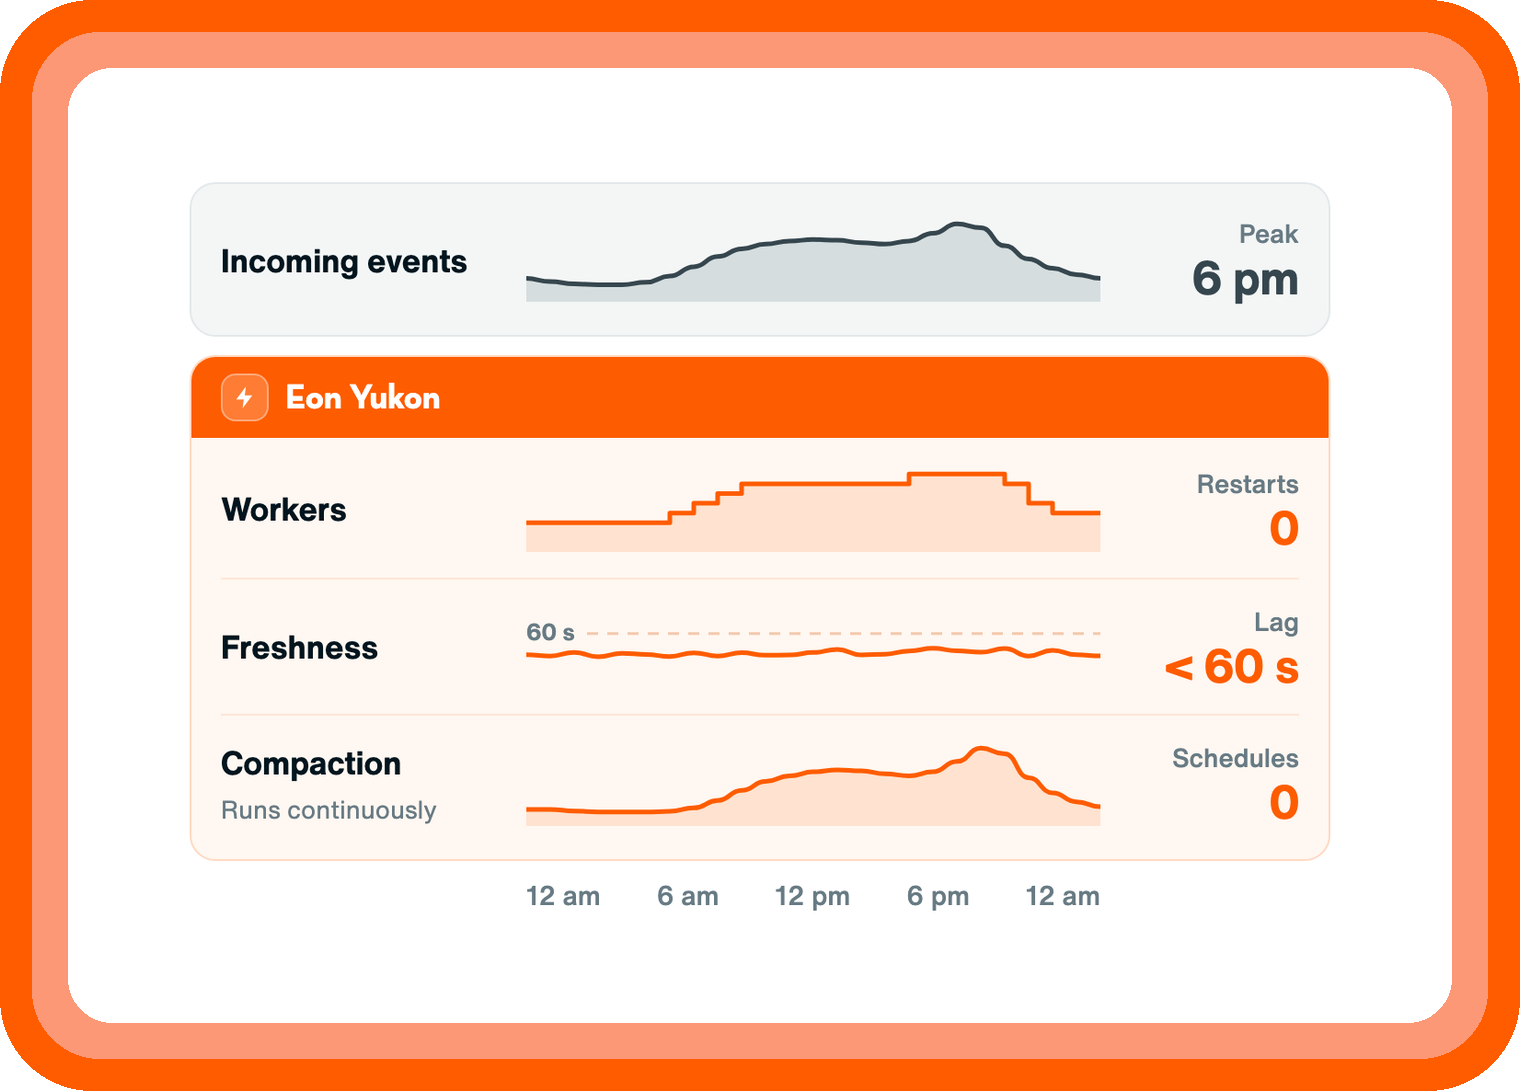
Eon Yukon scales with your traffic, keeping data flowing without restarts. There are no workers to size, checkpoint intervals to tune or processing state to manage.
Summaries that keep themselves current
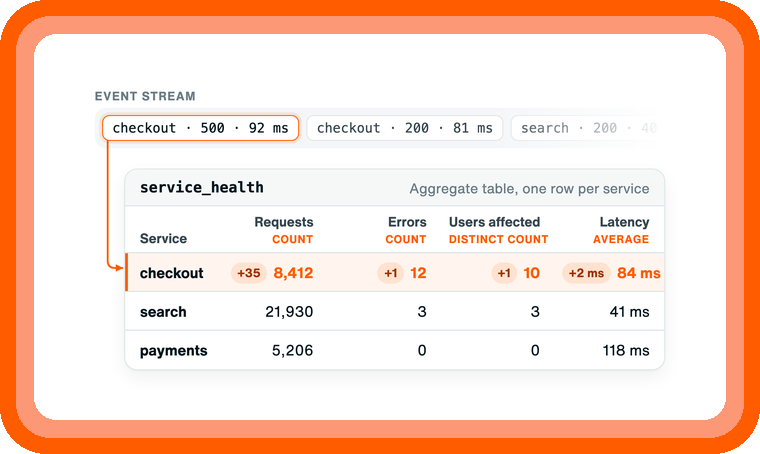
The aggregates you define update continuously alongside event records, in the same ingestion pass. Customer profiles, usage metrics and operational dashboards stay current without separate aggregation jobs, with summaries written to tables and served live with sub-millisecond reads through Eon Yukon.
Schema changes handled for you
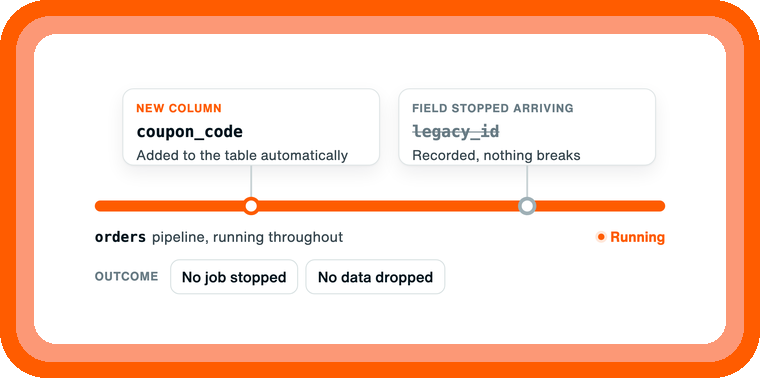
Eon picks up new fields and changed types upstream automatically and records what changed in every commit, so a schema change no longer stops a job or drops data.
Pipelines agents can build and watch
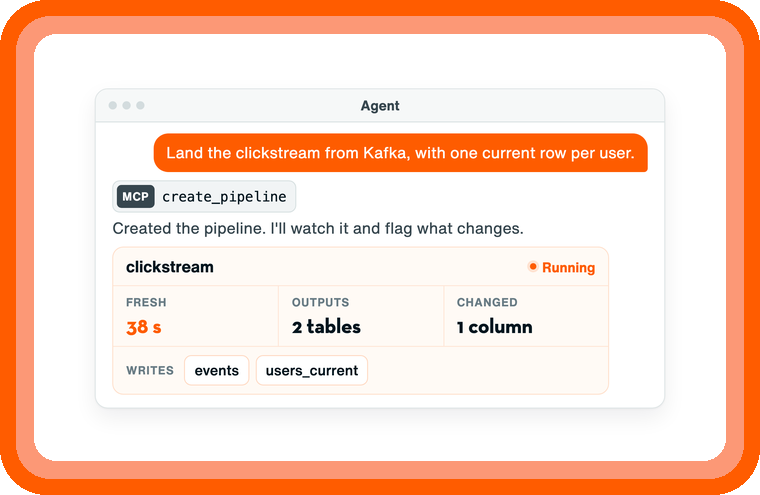
Agents create, change and watch pipelines over MCP. Every table carries Eon Yukon’s description of its grain, columns, joins and recent changes, so an agent knows what it built and what changed.
See how Eon works in your environment
Bring a pipeline your team maintains today and we will show you the same tables built by one Eon Yukon pipeline, with the jobs it replaces side by side.