Real-time analytics on data seconds old
Eon Yukon lands streams as clean, aggregated Iceberg tables within seconds, so dashboards, investigations and applications run on what is happening now.
Streaming data, batch answers
Events arrive in seconds, but the tables built from them are minutes or hours behind. Streaming jobs land raw appends, batch jobs merge and aggregate them later, and a separate cache serves the numbers applications need. By the time a dashboard shows a spike, a fraud pattern or a stalled feed, the moment to act on it has passed.
Freshness lost between jobs
Each hop from stream to bronze table to merged table to aggregate adds delay, so the freshest table is only as current as the slowest job.
Aggregates rebuilt from scratch
Scheduled jobs recompute customer profiles, usage metrics and operational dashboards, rescanning data that has not changed.
A second system for live numbers
Applications that need the current value by key read from Redis or Aerospike, filled by sync jobs that drift from the lake.
Stateful jobs to babysit
Windowed aggregations in Flink or Spark keep state and checkpoints to size, tune and recover, and skewed keys slow them down.
How Eon delivers real-time analytics
Eon Yukon reads each event once and, in the same pass, deduplicates it, applies updates and keeps windows, distinct counts and top-k current. Tables are queryable within seconds with serverless SQL or any Iceberg engine, and the same aggregates are readable by key in under 1 ms. Tables stay sorted and compacted, with no compaction jobs for your team to schedule. In Eon's public benchmarks, Eon used 4× to 7× less compute than Spark and Flink for ingestion and compaction combined.
Fresh, current tables from every stream
Kafka topics and object storage land as Apache Iceberg tables with upserts and deduplication applied, queryable within seconds. Historical records and current state are both ready to query.
Summaries that never need rebuilding
Configured aggregates update continuously in the same ingestion pass: windows, distinct counts and top-k. Dashboards and usage metrics stay current without separate aggregation jobs or state to babysit.
Live numbers for applications
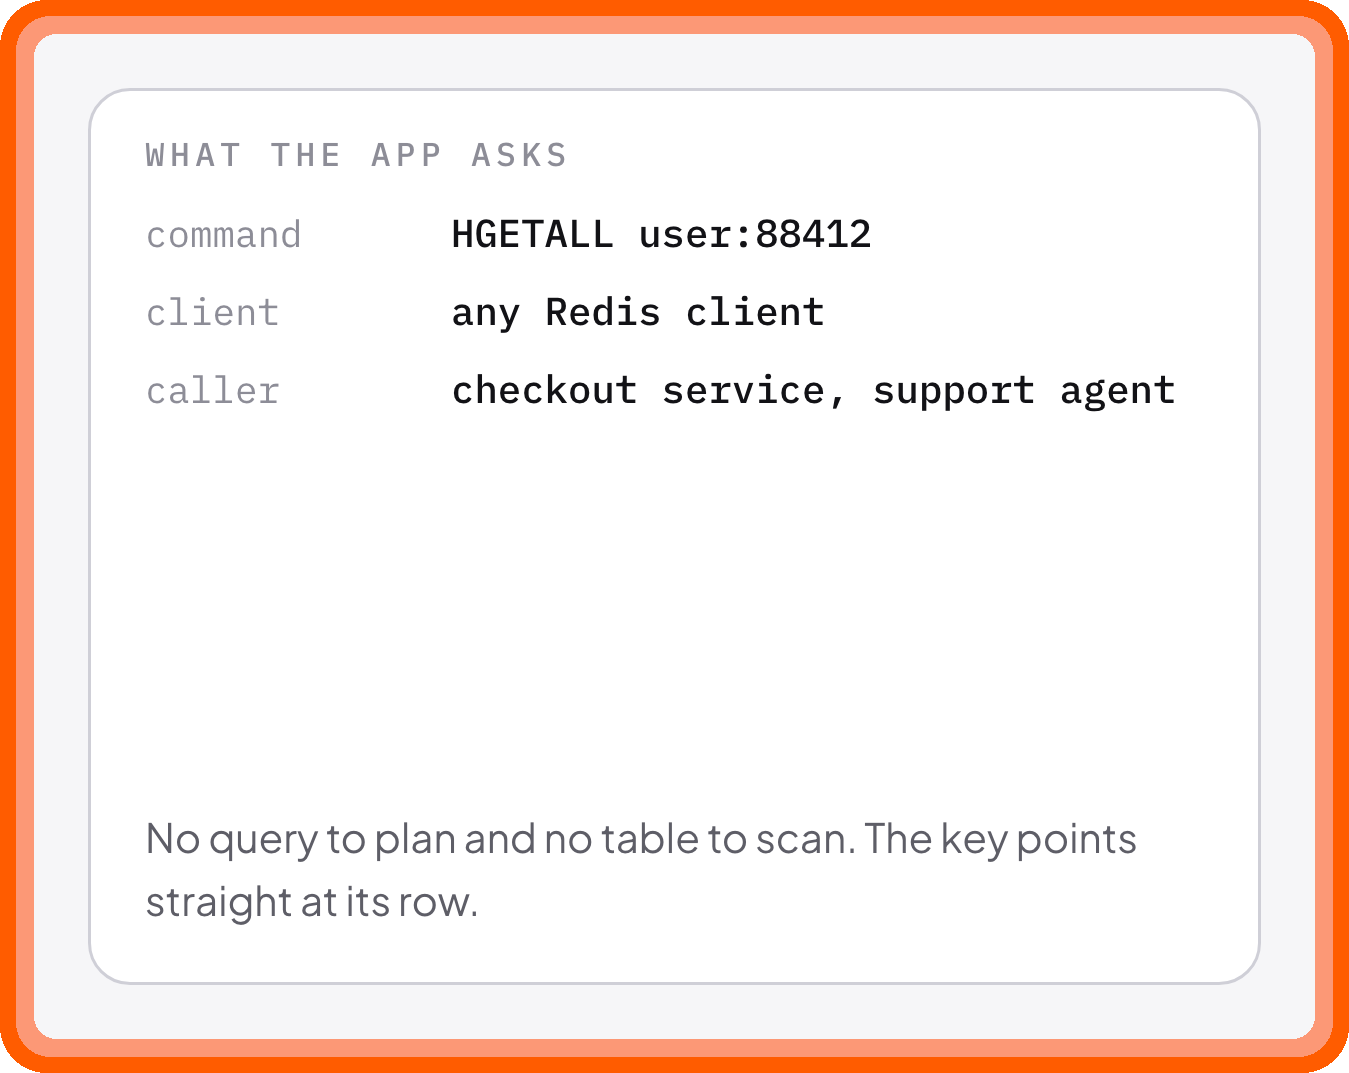
Read the current value for any key in under 1 ms over Eon Realtime's Redis-compatible API, with GET, MGET or HGETALL from any Redis client. The state is committed to object storage in a dedicated account in your region, shared with you, or in your own account with BYOC, so there is no cache to fill and no sync job to run.
Fast queries on fresh data
Eon Query plans serverless SQL in milliseconds from statistics written at ingest. Snowflake, Databricks, BigQuery and Trino read the same tables for BI.
See how Eon works in your environment
Bring a stream your dashboards wait on today and we will show you that data landing in Eon Yukon tables within seconds, with freshness compared side by side.