Streaming ingestion
From streams to query-ready tables within seconds.
Eon Yukon turns Kafka streams and cloud files into query-ready Iceberg tables, with processing and maintenance built in.
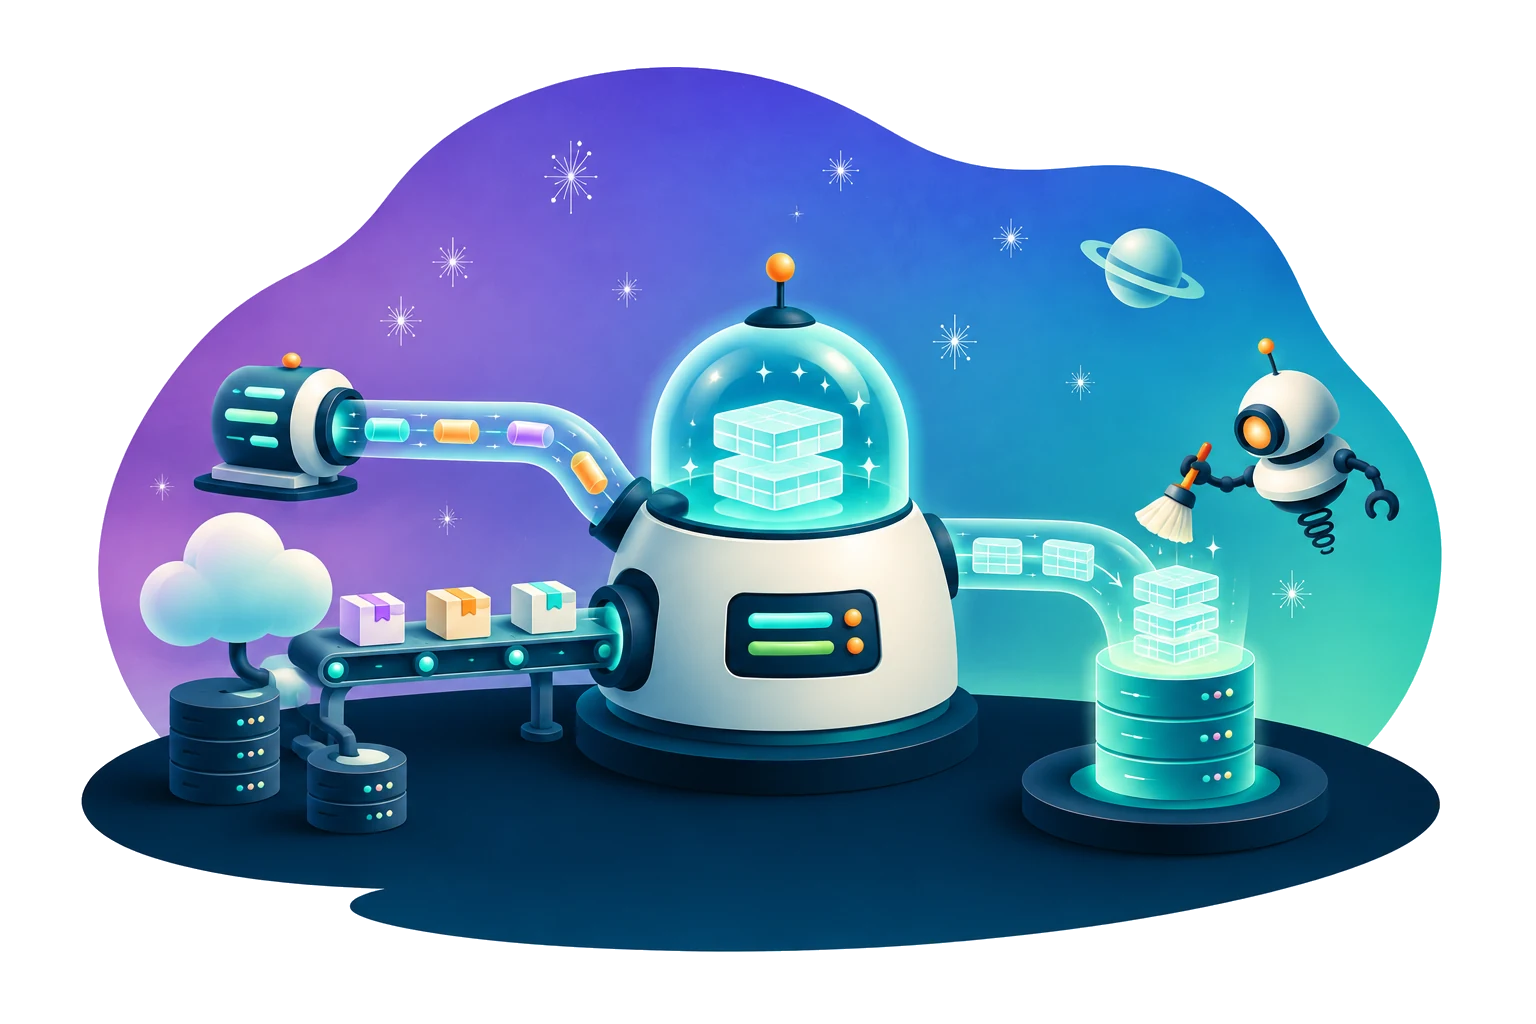
Prepare clean, current data as it arrives
Eon Yukon prepares fresh, query-ready data, with ongoing maintenance built in.
Get more from a single pass
Land events, apply updates and remove duplicates, or build live summaries. Choose the outputs you need, and Eon Yukon produces them in one pass over the incoming data.
Keep tables fast automatically
Eon Yukon continuously compacts and sorts your data, with snapshot and file cleanup built in. Your tables stay ready to query without separate maintenance jobs to schedule or manage.
Keep data flowing through uneven traffic
A busy customer, device or partition shouldn’t hold up your entire stream. Eon automatically distributes the work to keep data moving without manual tuning.
Use your data with the tools you choose
Your data lands as open Iceberg tables in your cloud storage. Query it with compatible engines without making another copy.
From incoming events to ready-to-use tables
Connect your sources, choose your outputs and let Eon Yukon handle the processing and ongoing maintenance.
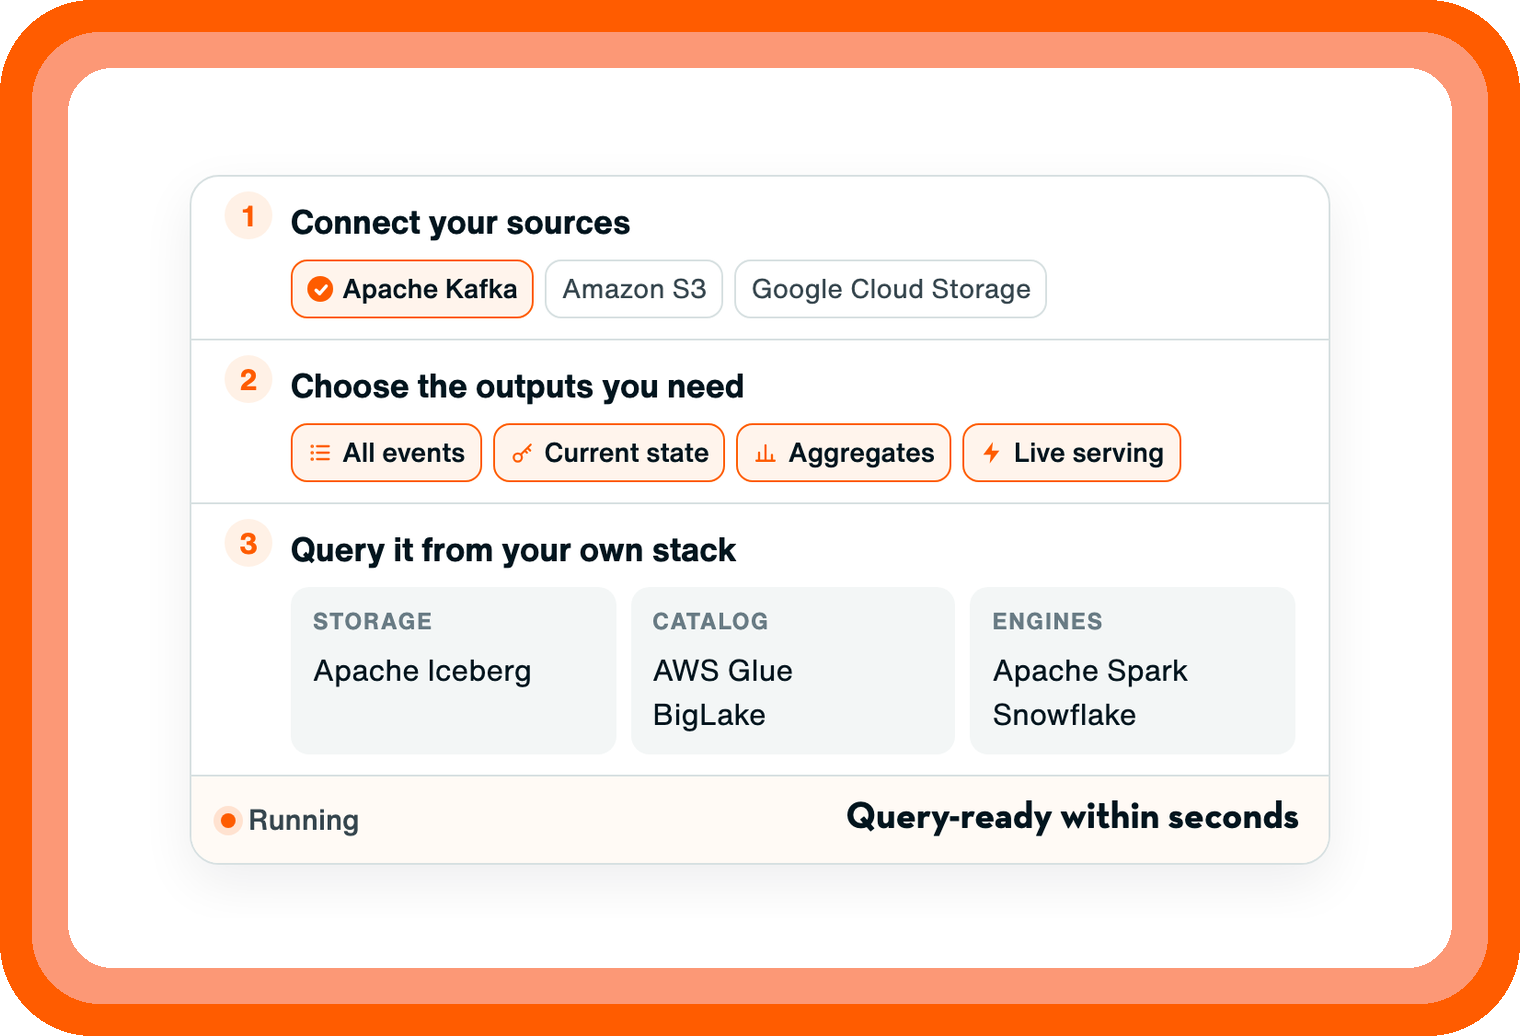
Bring events from Kafka or files from Amazon S3 and Google Cloud Storage. Eon Yukon handles ingestion as new data arrives.
Pick the tables you want: every event, one current row per key, or live summaries. Configure them directly or through your AI agents, and Eon Yukon produces them in one pass.
Query new data within seconds using the engines you already use, while Eon Yukon keeps compacting, sorting and cleaning up the tables as they grow.
Put streaming ingestion to work
01
Kafka to lakehouse, without the jobs
Replace separate ingestion, merge and maintenance jobs with one managed pipeline. Eon delivers query-ready lakehouse tables within seconds, using 4× to 7× less compute than Spark and Flink in our benchmarks. See Replace Spark and Flink pipelines.
02
Always-current tables
CDC and event streams carry every insert, update and delete for orders, users and devices. Eon Yukon merges them by key as they land, so the lake holds one current row per entity, ready for analytics and agents, with no batch merge to wait for.
03
Keep the full picture of AI activity
Capture model calls, traces and evaluations, with new events ready to query within seconds. Keep every event, or use smart sampling to preserve rare events while reducing volume. Give your team the detail to investigate failures, compare model behavior and improve agents.
04
Compute features once, serve them anywhere
Eon computes each feature as data lands. Applications can read new values within seconds, with reads in under 1 ms, and the same values become queryable in lakehouse tables within seconds. Models and applications use the same features, with no separate feature store to load and keep in sync.
See how Eon works in your environment
Bring a Kafka topic or a bucket of files you work with today and we will show you that data landing in query-ready Iceberg tables, with freshness and compute side by side.